Earlier stories
Every published Modelwire story, newest first. The homepage leads with the weekly overview and this week’s hottest; this is the full collection.
Quoting Boris Mann
Boris Mann challenges the marketing language around 'AI agents' as a meaningless metric, drawing a parallel to claiming productivity from raw tool counts rather than outcomes. The critique cuts at a core problem in the AI industry: vendors conflate deployment quantity with capability or value. For practitioners evaluating agent-based systems, this signals the need to move past headcount rhetoric toward measurable task completion and integration depth. The framing matters as enterprise adoption accelerates and agent frameworks proliferate.
Senses Wide Shut: A Representation-Action Gap in Omnimodal LLMs
Researchers have identified a critical failure mode in multimodal language models: the ability to detect when text contradicts sensory input. The IMAVB benchmark, spanning 500 video clips with controlled premise conflicts, reveals that eight open-source omnimodal LLMs and Gemini 3.1 Pro exhibit a representation-action gap, where internal representations capture sensory mismatches but models fail to flag them in output. This finding exposes a fundamental grounding weakness in systems marketed as perception-aware agents, suggesting that multimodal alignment remains incomplete despite joint video, audio, and text processing. The gap has immediate implications for deployment in safety-critical domains where hallucination detection is essential.62

NVIDIA’s New AI Is Fast For A Strange Reason
NVIDIA released Nemotron-3 Nano Omni, a multimodal model that achieves efficiency through an unconventional architectural choice revealed in the underlying research. The model consolidates vision, language, and reasoning into a single compact checkpoint, addressing the industry's push toward unified agents that don't require separate specialized models. This matters because it signals a shift away from modular stacking toward integrated designs that reduce latency and memory overhead, a constraint that shapes deployment economics across edge and cloud inference.
Anthropic courts a new kind of customer: small business owners
Anthropic is shifting its go-to-market strategy to capture the SMB segment, a move that signals intensifying competition for AI adoption beyond enterprise incumbents. This reflects a broader industry pivot: as frontier models commoditize and deployment costs drop, the addressable market expands downmarket. Success here would reshape LLM economics, forcing competitors to follow suit and potentially accelerating the timeline for AI-native workflows in small operations. The strategic play matters because SMB penetration often precedes enterprise lock-in and determines which vendor becomes the default platform.
RTLC -- Research, Teach-to-Learn, Critique: A three-stage prompting paradigm inspired by the Feynman Learning Technique that lifts LLM-as-judge accuracy on JudgeBench with no fine-tuning
Researchers have identified a critical weakness in LLM-as-judge systems, which now dominate evaluation of open-ended AI outputs, yet fail dramatically on objective correctness tasks in standard benchmarks. RTLC, a novel three-stage prompting method rooted in pedagogical scaffolding, substantially improves judge accuracy by orchestrating multiple independent reasoning paths and self-critique without requiring fine-tuning or external infrastructure. This addresses a foundational measurement problem: as AI evaluation shifts from automated metrics to LLM verdicts, the judges themselves must become more reliable, making this technique strategically relevant for anyone building evaluation pipelines or relying on LLM-based quality signals.62

Luma opens Uni-1.1 image model API at prices and quality matching OpenAI and Google
Luma's API launch for Uni-1.1 signals a consolidation of the image generation market around three dominant players. Ranking third on Arena benchmarks while matching OpenAI and Google's pricing underscores how quickly capability parity has compressed the competitive surface to cost and feature differentiation. The inclusion of web search, reasoning, and multi-image conditioning hints at the next battleground: integrated workflows rather than isolated model access. For practitioners, this represents a genuine alternative to established incumbents at scale.73
Beyond Perplexity: A Geometric and Spectral Study of Low-Rank Pre-Training
A new study challenges the standard metric for evaluating low-rank pre-training methods by demonstrating that validation perplexity masks meaningful differences in model behavior and internal structure. Researchers compared five low-rank approaches using geometric and spectral analysis, revealing that methods matching on perplexity can converge to fundamentally different loss landscape regions and learned representations. This finding matters for practitioners scaling LLM training on constrained hardware: perplexity parity may not guarantee equivalent downstream performance or robustness. The work reframes how the field should benchmark memory-efficient training, potentially shifting adoption decisions away from perplexity-only comparisons toward richer solution characterization.62
FlowCompile: An Optimizing Compiler for Structured LLM Workflows
FlowCompile reframes multi-agent LLM system optimization as a compilation problem rather than runtime routing. Instead of selecting model configurations per query, the approach pre-computes a globally optimized workflow graph before deployment, reducing the combinatorial explosion of choices across model selection, inference budgets, and agent topology. This shifts the optimization burden upstream, potentially unlocking better accuracy-latency tradeoffs for production agentic systems and influencing how teams architect complex reasoning pipelines.62
Amazon launches an AI shopping assistant for the search bar, powered by Alexa+
Amazon is consolidating its conversational shopping layer by replacing Rufus with a new Alexa-powered assistant embedded directly in search. This move signals Amazon's bet that LLM-driven product discovery can drive higher conversion than traditional keyword matching, while also tightening integration between its voice AI infrastructure and e-commerce core. The shift reflects broader retail AI strategy: personalized, context-aware shopping experiences powered by foundation models are becoming table stakes for major platforms competing on customer lifetime value.
Inducing Artificial Uncertainty in Language Models
As language models saturate training datasets and achieve high baseline accuracy, traditional uncertainty quantification methods face a critical bottleneck: they require labeled examples of genuine model failure to calibrate properly, yet high-performing LLMs rarely fail on seen data. This paper tackles the inverse problem by proposing methods to synthetically induce uncertainty in model predictions, enabling supervised training of calibration layers without waiting for naturally occurring hard cases. The work addresses a real safety infrastructure gap for deployment in high-stakes domains where confidence scores must reflect true epistemic limits rather than overconfident extrapolation.62
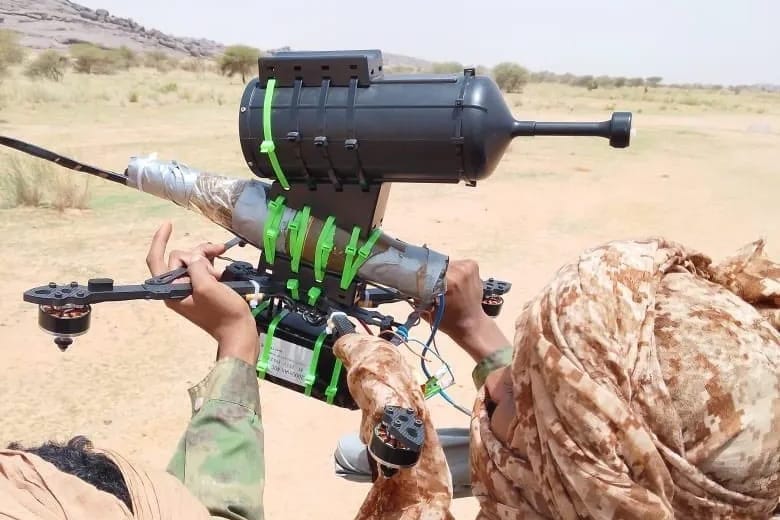
War and Data Centers Are Driving Up the Cost of Fiber Optic Cable
Fiber optic cable shortages driven by geopolitical conflict and massive datacenter buildouts are creating supply chain bottlenecks that threaten AI infrastructure expansion. As hyperscalers race to deploy LLM serving capacity and training clusters, competition for undersea and terrestrial fiber has intensified, pushing costs upward and potentially constraining the pace at which cloud providers can scale compute availability. This supply-side friction could reshape datacenter deployment timelines and regional AI service availability.69

Can AI Chatbots Reason Like Doctors?
OpenAI's large language model has demonstrated superior performance to practicing physicians on clinical reasoning benchmarks using real emergency department data, according to a Science publication. This result signals a potential inflection point in medical AI: moving beyond narrow, rule-based decision support toward general-purpose models that can navigate the ambiguity inherent in diagnosis and treatment planning. The finding arrives amid growing scrutiny of chatbot medical accuracy, raising questions about deployment readiness and the gap between benchmark success and clinical safety in high-stakes environments.
WhatsApp Adds Meta AI Chats That Are Built to Be Fully Private
Meta is positioning privacy as a competitive differentiator in conversational AI by rolling out Incognito Chat on WhatsApp, a feature that isolates user interactions from Meta's own infrastructure and logging systems. This move reflects growing tension between consumer privacy expectations and the data-collection economics that typically fund large language model services. For the AI industry, it signals that on-device or encrypted inference may become table stakes for mainstream adoption, particularly in messaging where users expect confidentiality. The strategic play matters less as a technical breakthrough and more as a market signal: even Meta, which built its empire on data leverage, recognizes that some user segments will demand genuine privacy guarantees before engaging with AI assistants at scale.65
Anthropic now has more business customers than OpenAI, according to Ramp data
Anthropic has surpassed OpenAI in verified business customer count for the first time, per Ramp's AI Index data. This milestone signals a meaningful shift in enterprise adoption patterns, suggesting that Claude's positioning on reliability and safety resonates with risk-conscious procurement teams. The crossover matters less as a vanity metric and more as evidence that the LLM market is fragmenting beyond OpenAI's historical dominance. For enterprise buyers, this validates Anthropic as a credible alternative; for investors, it underscores that first-mover advantage in consumer AI doesn't guarantee B2B stickiness.
Bosch, Researchers Develop AI for Humanoid Dexterity
Bosch and research collaborators have introduced a novel training methodology called 'touch dreaming' that dramatically improves robotic manipulation by simulating tactile feedback during model training. The 90.9% success-rate improvement signals a meaningful advance in embodied AI, where physical dexterity has long lagged vision and language capabilities. This bridges a critical gap for industrial automation and suggests that synthetic sensory simulation may unlock humanoid deployment at scale, reshaping expectations for robot labor in manufacturing and logistics.66
RealICU: Do LLM Agents Understand Long-Context ICU Data? A Benchmark Beyond Behavior Imitation
RealICU addresses a critical gap in LLM evaluation: existing clinical benchmarks treat physician actions as ground truth despite those decisions being made under incomplete information. This new benchmark uses hindsight annotation from senior physicians reviewing full patient trajectories, enabling more rigorous assessment of whether LLMs genuinely reason about complex medical states or merely imitate suboptimal historical behavior. The work signals growing sophistication in domain-specific AI evaluation, particularly for high-stakes settings where behavioral mimicry masks reasoning failures.62
China's AI suppliers can't keep up as critical component shortages hit production
China's AI hardware ecosystem faces a critical bottleneck as component scarcity and production constraints throttle capacity expansion. This supply-side friction directly impacts the pace at which Chinese AI labs and cloud providers can scale training infrastructure, potentially widening the gap between domestic capability development and global competitors who benefit from more diversified supply chains. The shortage signals that hardware availability, not algorithmic innovation, has become the binding constraint for near-term AI advancement in the region.73
Many-Shot CoT-ICL: Making In-Context Learning Truly Learn
Researchers challenge the assumption that many-shot in-context learning scales uniformly across all LLM types and task domains. The study reveals that chain-of-thought demonstrations behave unpredictably when scaled up on non-reasoning models, while reasoning-specialized LLMs benefit consistently. This finding reshapes how practitioners should architect prompt engineering strategies and suggests that model architecture and training objectives fundamentally alter how models absorb multi-example conditioning. The instability on general-purpose models has immediate implications for production deployments relying on long-context windows.62
Poppy debuts a proactive AI assistant to help organize your digital life
Poppy represents a maturing category of AI assistants that move beyond single-task chatbots to become ambient coordinators of personal information. By integrating calendar, email, and messaging APIs, the app delegates routine cognitive work—flagging deadlines, surfacing context, generating task lists—to language models operating over a user's actual data graph. This shift from query-response to proactive inference marks a subtle but significant landscape change: AI's value increasingly lies not in answering questions but in reducing decision friction across fragmented digital surfaces. For product teams, the play signals that consumer AI adoption hinges less on novelty and more on solving the coordination tax that knowledge workers face daily.
Podcast: The Chinese Deepfake Software Powering Scams
Haotian AI, a Chinese-language deepfake generation tool, has become a vector for financial fraud, signaling how synthetic media capabilities are outpacing detection and enforcement mechanisms in emerging markets. The proliferation of accessible deepfake software outside Western regulatory frameworks raises questions about asymmetric risk: while major labs debate safety, commodity tools already enable real-world harm at scale. This gap between capability democratization and governance capacity matters for anyone tracking where AI abuse happens first.65
Effective Context in Transformers: An Analysis of Fragmentation and Tokenization
Researchers have identified a fundamental tension in transformer architecture: the choice of tokenization scheme (bytes, characters, subwords) shapes what information models can extract within a fixed context window, even when representations are mathematically lossless. The paper introduces fragmentation theory to explain why finer-grained units can degrade prediction accuracy despite larger context allocations. This finding challenges assumptions underlying current tokenizer design and suggests that context-window scaling alone cannot overcome representation inefficiencies, with implications for how practitioners should balance tokenization granularity against computational budget.62
Software Developers Say AI Is Rotting Their Brains
Software developers are reporting cognitive decline tied to heavy reliance on AI coding assistants, raising questions about whether automation tools are atrophying core technical skills. The concern signals a potential long-term workforce risk: if AI handles routine problem-solving, practitioners may lose the deliberate practice needed to build and maintain expertise. This mirrors historical debates around calculator adoption and GPS navigation, but carries sharper stakes in a field where reasoning depth directly affects system reliability and security.65
Alexa is moving into Amazon.com
Amazon is embedding Alexa Plus, its LLM-powered assistant, directly into Amazon.com's search and shopping interface as Alexa for Shopping. This move signals a strategic pivot toward conversational commerce, where natural language queries replace traditional keyword search. The integration tests whether LLM assistants can drive higher conversion rates and customer engagement in e-commerce, a sector where AI adoption has lagged behind other verticals. For the broader AI landscape, this represents a major tech incumbent weaponizing proprietary LLM infrastructure to defend retail dominance against emerging AI-native shopping tools.
Assessing the Creativity of Large Language Models: Testing, Limits, and New Frontiers
Researchers challenge the validity of applying human creativity benchmarks to LLMs, arguing that standard psychological tests lack predictive power for machine creative output. This systematic study across writing, divergent thinking, and scientific ideation exposes a methodological gap in how the field evaluates model capabilities. The finding matters because it forces a reckoning: either the tests themselves need redesign for machine contexts, or the field has been misreporting creativity metrics. For practitioners building creative AI systems, this suggests current leaderboards may not reflect actual generative quality.62
Adaption aims big with AutoScientist, an AI tool that helps models train themselves
Adaption's AutoScientist automates the fine-tuning process, enabling models to self-optimize for domain-specific tasks without manual intervention. This addresses a persistent friction point in model deployment: the labor-intensive cycle of task-specific adaptation. If execution matches ambition, the tool could shift fine-tuning from a specialized engineering bottleneck into a scalable, repeatable workflow. The move signals growing competition in the model-customization layer, where reducing time-to-capability matters as much as raw model quality for enterprise adoption.
Archivists Turn to LLMs to Decipher Handwriting at Scale
Archivists are deploying large language models to unlock handwritten historical documents at scale, solving a decades-old AI challenge that has frustrated researchers since the 1960s. The shift from manual transcription to LLM-powered optical character recognition represents a practical convergence of cultural heritage work and modern AI capability, enabling scholars to access previously inaccessible primary sources. This use case demonstrates how general-purpose models are finding traction in specialized domains where traditional OCR failed, reshaping how institutions digitize and preserve knowledge.
AI startup Recursive emerges from stealth with $650 million to build self-improving AI
Recursive's $650M funding round signals serious capital backing for recursive self-improvement as a path to superintelligence, a technical approach that remains largely unproven at scale. The startup's emergence reflects investor appetite for foundational AI research outside established labs, though the core claim that recursive loops accelerate capability gains faster than alternative scaling methods lacks empirical validation in the public record. This matters for the landscape because it tests whether self-directed model improvement can outpace traditional scaling, and whether venture capital will sustain bets on speculative AI architectures amid regulatory uncertainty.80
Google is hiring hundreds of engineers to help customers adopt its AI
Google's expansion of implementation-focused engineering teams signals a critical bottleneck in enterprise AI adoption. While model capability has advanced rapidly, the gap between cutting-edge systems and productive customer deployment remains substantial enough to justify hundreds of dedicated staff. This shift reflects a maturing market where competitive advantage increasingly flows to vendors who can navigate the messy reality of integration, fine-tuning, and operational handoff rather than raw model performance alone. For enterprises evaluating AI vendors, this suggests Google is betting that adoption friction, not technology gaps, will determine market share.68
The Deployment Company, Back to the 70s, Apple and Intel
OpenAI's formation of a dedicated deployment subsidiary signals a strategic shift in how frontier labs will operationalize AI systems at scale. Rather than licensing models to third parties, the major labs are building vertically integrated infrastructure to control the full stack from training through production. This top-down deployment model mirrors historical patterns in computing infrastructure and suggests AI's real-world impact will be shaped by which organizations can sustain the capital and operational complexity of end-to-end systems. The parallel moves by competing labs indicate this is becoming table stakes for maintaining competitive advantage.80