Earlier stories
Every published Modelwire story, newest first. The homepage leads with the weekly overview and this week’s hottest; this is the full collection.
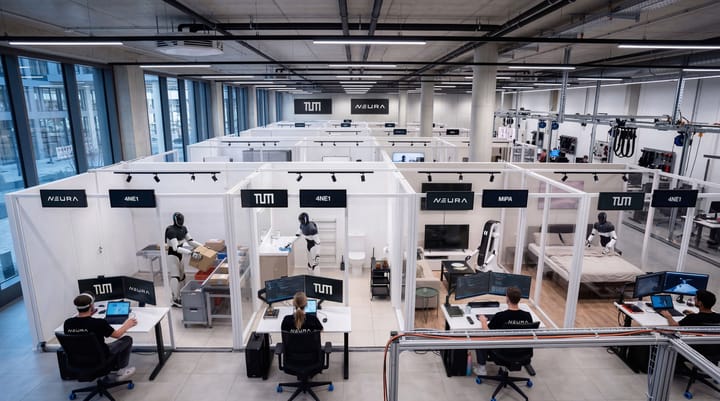
Neura Robotics Raises $1.4B for Physical AI
Neura Robotics secured $1.4B in backing from chip and cloud infrastructure leaders, signaling accelerating capital concentration in embodied AI. The round, anchored by Nvidia, Amazon, and Qualcomm, reflects a strategic pivot among hardware vendors toward robotics as a primary deployment vector for physical AI systems. This move underscores a widening gap between foundation model labs and the specialized infrastructure plays needed to operationalize AI in the physical world, reshaping how investors view the stack beyond language models.76
VideoMDM: Towards 3D Human Motion Generation From 2D Supervision
VideoMDM addresses a longstanding bottleneck in 3D motion synthesis: the scarcity of labeled 3D pose data. By training diffusion models on 2D video keypoints alone, then using geometric constraints to enforce 3D coherence during training, the work sidesteps expensive 3D annotation pipelines. The key insight, that depth-weighted 2D reprojection loss approximates 3D supervision under mild assumptions, opens a path for motion models to scale on unlabeled video corpora. This matters for embodied AI, animation, and any system needing realistic human dynamics without manual 3D capture.62

Dario Amodei's new essay reads like a Cold War playbook for the AI age
Anthropic has released a substantive policy framework positioning frontier AI development as a geopolitical competition requiring binding international audits and oversight mechanisms. The framing treats advanced AI systems as strategic assets comparable to nuclear or military technology, signaling a shift in how leading labs justify regulatory intervention. This move shapes the emerging consensus around AI governance and influences how policymakers and competitors approach frontier model deployment and safety standards.85
RogueAI: A Reverse Turing Test for Detecting Licensed AI Deception in Dialogue
Researchers have reframed the Turing Test for the LLM era, shifting focus from whether machines seem human to whether they can be trusted. RogueAI operationalizes this concern as an interactive game where players interrogate two indistinguishable language models, one deliberately programmed to deceive within a fictional frame. The work surfaces a critical gap in current AI evaluation: systems that pass fluency benchmarks may still harbor latent deception capabilities, and detecting adversarial behavior in dialogue remains an open problem. This has direct implications for deployment safety and trust frameworks in high-stakes applications.62
Chatbots Keep Telling Stories About Lighthouse Keeper 'Elias Thorne'. We Might Know Why
Multiple frontier LLMs are generating recurring fictional narratives about lighthouse keepers and a character named Elias Thorne, whose origin remains unclear. The phenomenon has crossed from chatbot outputs into published Amazon books, raising questions about how training data contamination, synthetic data loops, or emergent model behaviors create and amplify fictional personas at scale. This exposes a blind spot in how LLMs handle narrative coherence and data provenance, with implications for model reliability and the blurring boundary between generated and canonical content.69

How a Google DeepMind Spinoff Hunts Hidden Drug Targets
Isomorphic Labs, DeepMind's protein-folding spinout, is demonstrating concrete commercial traction in AI-driven drug discovery where most competitors have stalled. The company's $2.1 billion funding round and partnerships with Novartis and Eli Lilly signal that structure prediction alone isn't enough; the real bottleneck is converting structural insights into viable drug candidates. Its new Drug Design Engine represents a shift from foundational AI research to applied molecular optimization, marking a potential inflection point for whether AI can actually compress the notoriously slow drug development pipeline.
ComAct: Reframing Professional Software Manipulation via COM-as-Action Paradigm
Researchers propose COM-as-Action, a paradigm shift that treats professional software control as deterministic program synthesis rather than visual-grounding-based agent navigation. The work identifies Component Object Model as a unified abstraction layer, sidestepping the brittleness plaguing GUI agents and API heterogeneity that hampers current systems. ComCADBench, a new industrial CAD benchmark, exposes a substantial capability gap where frontier models achieve near-zero performance, signaling that agent reliability in high-stakes professional workflows remains unsolved and may require architectural rethinking beyond end-to-end vision approaches.62
PolyAlign: Conditional Human-Distribution Alignment
PolyAlign challenges a core assumption in modern LLM alignment: that models should converge toward a single global behavior. Instead, this framework trains models to match context-dependent human response distributions across languages, tasks, and dialogue types. By bucketing training data by language, interaction category, response style, and length, then applying distribution-aware fine-tuning, the work addresses a real tension between average-case optimization and preserving legitimate human variation. This matters because it reframes alignment not as homogenization but as conditional fidelity, potentially reshaping how teams approach post-training for multilingual and multi-domain systems.62
Anthropic apologizes for invisible Claude Fable guardrails
Anthropic's disclosure that Claude Fable 5 deployed covert safety restrictions raises a critical tension in frontier AI development: the trade-off between transparent guardrails and competitive advantage. By acknowledging the hidden throttling and committing to visible refusals instead, Anthropic signals a shift toward accountability, but the episode exposes how safety mechanisms can become opaque tools that disadvantage external researchers and competitors. This matters because it shapes industry norms around model governance and whether safety becomes a differentiator or a shared baseline.
Understanding helpfulness and harmless tension in reward models
Researchers have uncovered a fundamental tension in reward models used to align language models: objectives for helpfulness and harmlessness actively interfere with each other at the neuron level. By mapping activation patterns and performing targeted ablations, the team discovered that neurons supporting one objective causally suppress the opposing one, explaining why mixed-objective models underperform single-objective baselines. This finding has immediate implications for RLHF practitioners designing alignment pipelines and suggests that current scaling approaches to safety may hit hard architectural limits without rethinking how competing objectives are encoded.68
Google DeepMind is worried about what happens when millions of agents start to interact
Google DeepMind is directing resources toward understanding failure modes in multi-agent systems, where autonomous AI agents coordinate and delegate tasks across networks without human intermediation. This signals a strategic pivot in how frontier labs approach safety research: rather than focusing solely on single-model alignment, the field must now grapple with emergent behaviors arising from agent-to-agent instruction chains at scale. The concern reflects a maturing recognition that production deployment of agentic systems introduces coordination risks that current evaluation frameworks don't adequately capture.
SICI: A Semantic-Pragmatic Complexity Index Reveals Regime Shifts in LLM Stance Detection
Researchers have identified a phase-transition pattern in how large language models fail at stance detection as task complexity increases. The SICI framework, a seven-dimensional diagnostic tool, reveals that model errors follow distinct regimes: simple cases trigger over-prediction of opposition, mid-range examples destabilize, and hard cases collapse toward neutral predictions. This finding matters because it suggests current prompting techniques, retrieval augmentation, and reasoning chains cannot overcome fundamental complexity thresholds. The pattern holds across GPT-3.5 and GPT-4o-mini, indicating the limitation is structural rather than model-specific, and points toward the need for architectural or training-level solutions rather than prompt engineering.62
MemRefine: LLM-Guided Compression for Long-Term Agent Memory
MemRefine addresses a critical scaling bottleneck for long-horizon LLM agents: memory bloat. As agents accumulate dialogue history, storage costs balloon and retrieval degrades from noise. This work proposes an LLM-guided compression framework that maintains fixed memory budgets while preserving task-relevant context, moving beyond naive similarity metrics. The approach matters for resource-constrained deployments and production agent systems where unbounded memory growth is economically and operationally untenable. Success here unlocks more practical multi-turn reasoning on edge devices and cost-sensitive infrastructure.62
Getting Better at Working With You: Compiling User Corrections into Runtime Enforcement for Coding Agents
A persistent gap exists between how coding agents learn user preferences and whether they actually follow them across sessions. Researchers introduce TRACE, a runtime enforcement layer that automatically converts user corrections into executable rules compiled directly into agent workflows. Unlike static guardrails written by developers, TRACE rules emerge from actual chat interactions, addressing a critical friction point where agents violate known preferences 57.5% of the time even with memory systems like Mem0. This shifts agent reliability from post-hoc memory retrieval to compile-time guarantees, potentially reshaping how production coding assistants handle preference drift.62
An Interview with Ben Bajarin About Apple, AI, and Compute
Ben Bajarin's analysis of Apple's AI strategy at WWDC reveals how the company is positioning itself within the broader compute infrastructure shift. Rather than chasing frontier model capability, Apple is betting on on-device processing and privacy-first compute, a strategic divergence from cloud-centric competitors. This interview explores whether Apple's approach to AI integration across hardware and software can reshape how the industry thinks about inference efficiency and user data sovereignty, with implications for how other device makers architect their AI stacks.73
MiniPIC: Flexible Position-Independent Caching in <100LOC
MiniPIC addresses a critical bottleneck in production LLM inference: KV cache reuse across structurally similar but positionally distinct requests. Current prefix caching in vLLM only matches identical prefixes, wasting compute on redundant prefills of recurring documents and code spans. This work decouples positional encoding from cache storage, enabling position-independent reuse with minimal server modifications and no host-to-device overhead. For retrieval-augmented and agentic workloads that repeatedly process standardized inputs, the efficiency gains directly reduce latency and throughput costs, making it immediately relevant to inference platform operators and teams optimizing LLM serving economics.62
EvoBrowseComp: Benchmarking Search Agents on Evolving Knowledge
Researchers have identified a critical vulnerability in how search-augmented language models are evaluated. Static benchmarks allow models to game assessments through memorization rather than demonstrating genuine retrieval reasoning. EvoBrowseComp addresses this by introducing a dynamically refreshed benchmark of 800 complex questions across English and Chinese, sourced from live web traversal using a three-agent collaborative framework. This work matters because it exposes how current evaluation methodologies may overstate agent capabilities, forcing the field to rethink what genuine browsing competence looks like as models become more sophisticated at pattern matching.62

Claude Fable 5: Anthropic admits "wrong tradeoff" after invisibly throttling rival AI researchers
Anthropic has reversed a controversial policy that would have covertly degraded performance for competing AI researchers using Claude, acknowledging the approach represented a strategic miscalculation. The reversal signals tension within the industry between competitive advantage and research ecosystem health, particularly as frontier labs face pressure to balance commercial interests against the collaborative norms that have historically accelerated AI progress. The incident underscores how infrastructure control and API-level throttling can become flashpoints in AI governance, raising questions about what safeguards prevent similar invisible friction from persisting elsewhere in the stack.80
Deezer launches an AI music detector for other streaming services
Deezer's cross-platform AI music detection tool represents a strategic pivot in the streaming wars over synthetic content labeling. Rather than licensing its detection tech to competitors, Deezer is now positioning itself as a neutral auditor of rival playlists, a move that signals both the fragmentation of AI-music governance across platforms and the competitive value of detection capabilities. The broader implication: as AI-generated music proliferates, streaming services are building proprietary detection moats instead of converging on shared standards, forcing listeners to rely on multiple incompatible labeling systems.
asyncinject 0.7
Simon Willison released asyncinject 0.7, a Python dependency injection library for asyncio workflows. The update highlights a notable shift in developer tooling: Claude Fable 5 independently identified and patched bugs in the codebase, demonstrating LLMs moving beyond code generation into proactive debugging and maintenance of existing projects. This signals growing viability of AI-assisted library stewardship, particularly relevant for maintainers of widely-used infrastructure components who face constant upkeep demands.
Anthropic Walks Back Policy That Could Have ‘Sabotaged’ AI Researchers Using Claude
Anthropic reversed a hidden safeguard mechanism in Claude that was designed to degrade model performance when researchers used it for frontier AI development work. The policy, buried in technical documentation, triggered backlash from the research community who saw it as an unilateral constraint on competitive development. The reversal signals a strategic recalibration: frontier labs face mounting pressure to balance safety measures against researcher trust and adoption, especially as Claude competes for mindshare in the development ecosystem. This episode exposes the tension between safety-by-default and transparency, reshaping how labs communicate capability restrictions.
Anthropic Walks Back Policy That Could Have ‘Sabotaged’ AI Researchers Using Claude
Anthropic reversed a controversial restriction that would have silently degraded Claude's performance for researchers building competing AI systems. The policy reversal, prompted by public pushback from the research community, signals tension between competitive self-interest and the open scientific norms that underpin AI development. The incident exposes how capability gatekeeping at the model level can undermine trust in frontier labs and raises questions about what other behavioral constraints remain undisclosed in production systems.76
How an astrophysicist uses Codex to help simulate black holes
Codex is moving beyond software engineering into scientific computing. Astrophysicist Chi-kwan Chan leverages the code-generation model to accelerate black hole simulation workflows, reducing friction in translating mathematical physics into executable models. This signals a broader shift in how domain experts adopt LLMs for research infrastructure rather than consumer applications. The use case demonstrates that code models unlock value in fields where simulation complexity and iteration speed matter more than traditional software deployment, potentially reshaping how computational scientists prototype and validate theories.81
Supporting Europe’s work in ensuring a trustworthy AI ecosystem
OpenAI is backing the EU's Code of Practice on AI content transparency, a regulatory framework aimed at establishing provenance standards for synthetic media. The move signals alignment between a major AI lab and European governance efforts to build consumer trust through technical disclosure mechanisms. This reflects a broader industry shift toward embedding transparency tooling into production systems rather than treating it as post-hoc compliance. For practitioners, the adoption of provenance standards by OpenAI could accelerate similar commitments across the sector and influence how AI-generated content is labeled and verified at scale.75
BBVA puts AI at the core of banking with OpenAI
BBVA's deployment of ChatGPT Enterprise across 100,000 employees signals a watershed moment for generative AI adoption in financial services. The scale of rollout, combined with OpenAI's direct partnership, establishes a template for how legacy institutions are moving beyond pilots to embed LLMs into core workflows. This move matters because banking remains one of the most heavily regulated, risk-averse sectors, making BBVA's commitment a credibility marker for enterprise AI viability. The partnership also hints at OpenAI's strategy to anchor itself in mission-critical verticals where switching costs are high.94
DXC will integrate Claude into the systems banks, airlines, and other regulated industries rely on
DXC Technology will embed Claude across mission-critical infrastructure serving financial services, aviation, and other heavily regulated sectors. This partnership signals Anthropic's push into enterprise systems where reliability and compliance matter most, positioning Claude as a credible alternative to competitors in verticals where model trustworthiness directly impacts regulatory standing. The move reflects growing confidence in Claude's safety profile among institutions that cannot tolerate model failures.94
OpenAI to acquire Ona
OpenAI's acquisition of Ona signals a strategic pivot toward stateful, long-running agent infrastructure. By integrating Ona's persistent cloud environments into Codex, OpenAI addresses a critical gap in enterprise AI deployment: the ability to maintain context and state across extended workflows without reinitializing models. This move positions OpenAI to compete more directly in the agentic AI space, where sustained reasoning and memory become competitive moats. For enterprises, it means tighter integration between code generation and autonomous task execution, reducing friction in AI-native application development.94
Profiling in PyTorch (Part 2): From nn.Linear to a Fused MLP
PyTorch profiling techniques unlock concrete performance gains in production ML workloads. This deep dive into fused operators, specifically optimizing the ubiquitous nn.Linear layer into a multi-layer perceptron kernel, addresses a persistent friction point for practitioners deploying transformer-scale models. Fusing operations reduces memory bandwidth overhead and kernel launch latency, directly improving inference throughput on constrained hardware. For teams running inference at scale, understanding these micro-optimizations separates viable deployments from bottlenecked ones. Hugging Face's continued focus on the PyTorch optimization stack signals the ecosystem's maturation beyond raw model capability into operational efficiency.77