Earlier stories
Every published Modelwire story, newest first. The homepage leads with the weekly overview and this week’s hottest; this is the full collection.
GPT-5.6 Sol powers SQL-based game engine prototype
Peter Gostev used GPT-5.6 Sol to build DOOMQL, a proof-of-concept that replaces traditional game engines with SQLite as the core runtime. The project demonstrates how modern LLMs can tackle unconventional architectural problems: SQL queries now handle collision detection, enemy AI, rendering, and player movement in a playable Doom-like terminal game. This signals a shift in how developers think about LLM-assisted systems design, moving beyond chatbots toward using AI to explore radical reimaginings of foundational software patterns.
Willison measures AI coding agent impact via Datasette commit history
Simon Willison used GitHub's code-frequency metrics to measure the tangible impact of advanced AI coding agents and Opus 4.5-class models on his own development velocity. By analyzing commit patterns in Datasette across eight years, Willison created a real-world case study showing how frontier LLMs are reshaping individual developer productivity. This anecdotal but credible observation from a respected open-source maintainer offers concrete evidence of how AI tooling is accelerating code output at scale, providing insiders with a practical lens on AI's near-term economic impact beyond benchmark claims.
Apple embeds Siri as iOS 27 core infrastructure
Apple is repositioning Siri from a narrow voice-command tool into a foundational AI layer across iOS 27, signaling a strategic shift toward on-device intelligence as the primary interface paradigm. This move reflects the broader industry pivot away from cloud-dependent assistants toward locally-integrated AI that handles routine tasks, system navigation, and contextual reasoning. For device makers competing on AI differentiation, the stakes are now whether assistants can deliver meaningful utility beyond novelty, and whether tight OS integration becomes the decisive advantage over standalone LLM applications.69
Nadella warns enterprises against relying on proprietary AI models
Microsoft's CEO is publicly challenging the enterprise adoption of closed third-party AI models, signaling a strategic pivot toward alternative approaches. This move reflects growing tension within the AI ecosystem over vendor lock-in, model transparency, and cost structures that favor proprietary solutions. For enterprises, the warning underscores mounting pressure to evaluate open-source alternatives and internal deployment strategies rather than defaulting to commercial API providers. The statement carries weight given Microsoft's own substantial investments in OpenAI, making it a notable repositioning that could influence how Fortune 500 companies architect their AI infrastructure.
Apple embeds generative AI deeper into iOS 27 with upgraded Siri
Apple's iOS 27 public beta marks a significant shift in on-device AI integration, with Siri receiving substantial capability upgrades that reshape how users interact with their phones. The rollout signals Apple's strategy to embed generative AI directly into consumer hardware rather than relying on cloud-dependent services, positioning the company alongside competitors racing to localize AI workloads. Early testing suggests these improvements move beyond incremental refinement, potentially influencing how other device makers approach AI feature parity and user expectations around intelligent assistants.
Apple sues OpenAI over alleged insider trade secret theft
Apple's lawsuit against OpenAI over alleged trade secret theft by a former engineer marks an escalation in IP disputes within the AI industry. The case hinges on whether OpenAI knowingly conspired with departing Apple staff to access proprietary information, raising questions about talent mobility and competitive safeguards at frontier labs. This signals growing legal friction as AI companies compete for engineering talent and technical advantage, with implications for how the sector manages employee transitions and confidentiality agreements.
Apple sues OpenAI over alleged trade secret theft and insider recruitment
Apple's lawsuit against OpenAI escalates the competitive tension between hardware makers and AI labs over talent and intellectual property. The complaint alleges systematic efforts to access Apple systems and recruit engineers with insider knowledge, signaling how AI companies are now competing aggressively for specialized talent and proprietary information. This case reflects a broader shift in AI industry dynamics where frontier labs view access to device ecosystems and engineering expertise as critical competitive assets, raising questions about hiring practices and IP protection across the sector.
Engram bets $98M on continual learning over long context windows
Engram's $98M funding round signals industry momentum behind continual learning as a path beyond long-context limitations. The startup's approach compresses knowledge directly into model weights rather than relying on retrieval or context windows, addressing a fundamental constraint in how LLMs retain and build on experience. This challenges the current RAG-dominated architecture and suggests a shift toward models that genuinely adapt over time, with implications for personalized AI agents and token efficiency as a core intelligence metric.73
Anthropic investigates whether AI models experience pain
Anthropic's latest research into machine sentience and pain perception in AI models reflects a strategic pivot toward safety and interpretability work that distinguishes the frontier lab from competitors focused purely on capability scaling. The investigation signals growing insider concern about anthropomorphizing AI systems and establishing empirical baselines for welfare considerations, a move that reshapes how the field evaluates model behavior beyond benchmark performance. This positions Anthropic as the primary institutional voice pushing the industry toward mechanistic understanding of model internals, influencing both research agendas and regulatory framings around AI development.
First survey maps metacognition landscape across language models
A comprehensive survey maps metacognition in large language models for the first time, establishing a taxonomy of how LLMs can develop self-awareness about their own reasoning and limitations. The work addresses a critical gap: while LLMs excel at task execution, their capacity for introspection remains poorly understood. Metacognitive abilities directly impact system reliability, transparency, and reasoning robustness. This foundational overview matters because it charts how future models might self-correct, flag uncertainty, and improve decision-making without external intervention. For AI builders, this frames metacognition as essential infrastructure for trustworthy deployment.62
Transformers learn inductive reasoning on low-dimensional manifolds
Researchers have developed a theoretical framework proving that Transformer attention models learn inductive reasoning through dynamics confined to a low-dimensional invariant manifold. This work unifies previously disparate synthetic tasks like in-context n-grams and multi-hop reasoning under a single mathematical lens, reducing millions of parameters to a handful of interpretable coordinates. The finding matters because it bridges the gap between empirical Transformer behavior and formal theory, enabling researchers to predict and manipulate learning trajectories without exhaustive simulation. For practitioners, this suggests inductive reasoning emerges through predictable geometric structures rather than opaque parameter interactions, potentially accelerating interpretability work and model design.62

Retargeting and RL combine for single-demo robot hand learning
Researchers have developed REGRIND, a pipeline that combines human motion retargeting with reinforcement learning to train robot hands for complex manipulation tasks from minimal demonstrations. The approach adapts a successful recipe from whole-body humanoid control, retargeting human hand-object interactions into robot-executable references while preserving spatial and contact constraints, then using residual RL to refine tracking in simulation before real-world transfer. This work addresses a critical gap in embodied AI: while imitation-guided RL has scaled humanoid locomotion, dexterous manipulation demands precise contact-mode regulation that standard retargeting alone cannot solve. The minimalist design and single-demo learning requirement suggest a practical path toward more capable robotic hands without massive labeled datasets.62
Mechanistic study reveals how LLM judges encode bias in hidden layers
Researchers have moved beyond surface-level input perturbations to expose how LLM judges encode bias in their internal representations. By analyzing activation patterns across seven judges and nine benchmarks, they discovered that biased inputs cluster along low-dimensional, type-specific subspaces in hidden layers, and that steering these representations directly controls scoring direction. This mechanistic account offers a new lever for bias mitigation beyond prompt engineering, with implications for anyone deploying LLMs for evaluation, ranking, or comparative assessment tasks where fairness matters.62

OpenAI shifts prompting guidance toward outcome-first, away from rigid formulas
OpenAI has published a user-focused prompting framework that deprioritizes rigid methodologies in favor of outcome-driven instruction. The guide introduces four optional components (goal, context, format, constraints) and emphasizes describing desired results rather than prescribing execution paths. This represents a strategic shift toward accessibility, lowering the barrier for non-technical users to extract value from both conversational and code-generation models under a unified mental model. The move signals OpenAI's confidence in model robustness while acknowledging that effective prompting remains more art than science for mainstream adoption.68
New benchmark exposes LLM weakness in graduate-level mathematical reasoning
Researchers have released AdvancedMathBench, a rigorous evaluation suite that exposes a critical gap in LLM capabilities: while models excel at high-school and competition mathematics, their performance on graduate-level proofs remains largely unmeasured. The benchmark's 296 problems span undergraduate through doctoral qualifying exams, paired with automated verification tools that assess reasoning validity rather than just final answers. This matters because existing benchmarks lack disciplinary breadth and rely on coarse correctness judgments, obscuring whether models truly understand advanced mathematical logic or merely pattern-match. The work signals growing pressure within the research community to move beyond surface-level performance metrics toward deeper evaluation of reasoning integrity, a shift that will likely reshape how labs benchmark reasoning capabilities going forward.62
Quantum neural networks vulnerable to adaptive backdoor attacks
Researchers have identified a critical vulnerability in quantum neural networks where attackers can embed dynamic, input-dependent backdoors that evade traditional defenses. Unlike classical neural network backdoors that rely on fixed triggers, this quantum variant adapts to each poisoned input, exploiting measurement collapse to hide malicious behavior in compressed classical outputs. The finding exposes a fundamental security gap in near-term quantum machine learning systems and suggests that quantum-specific attack vectors may outpace existing mitigation strategies, raising urgent questions about QNN deployment in sensitive applications.62
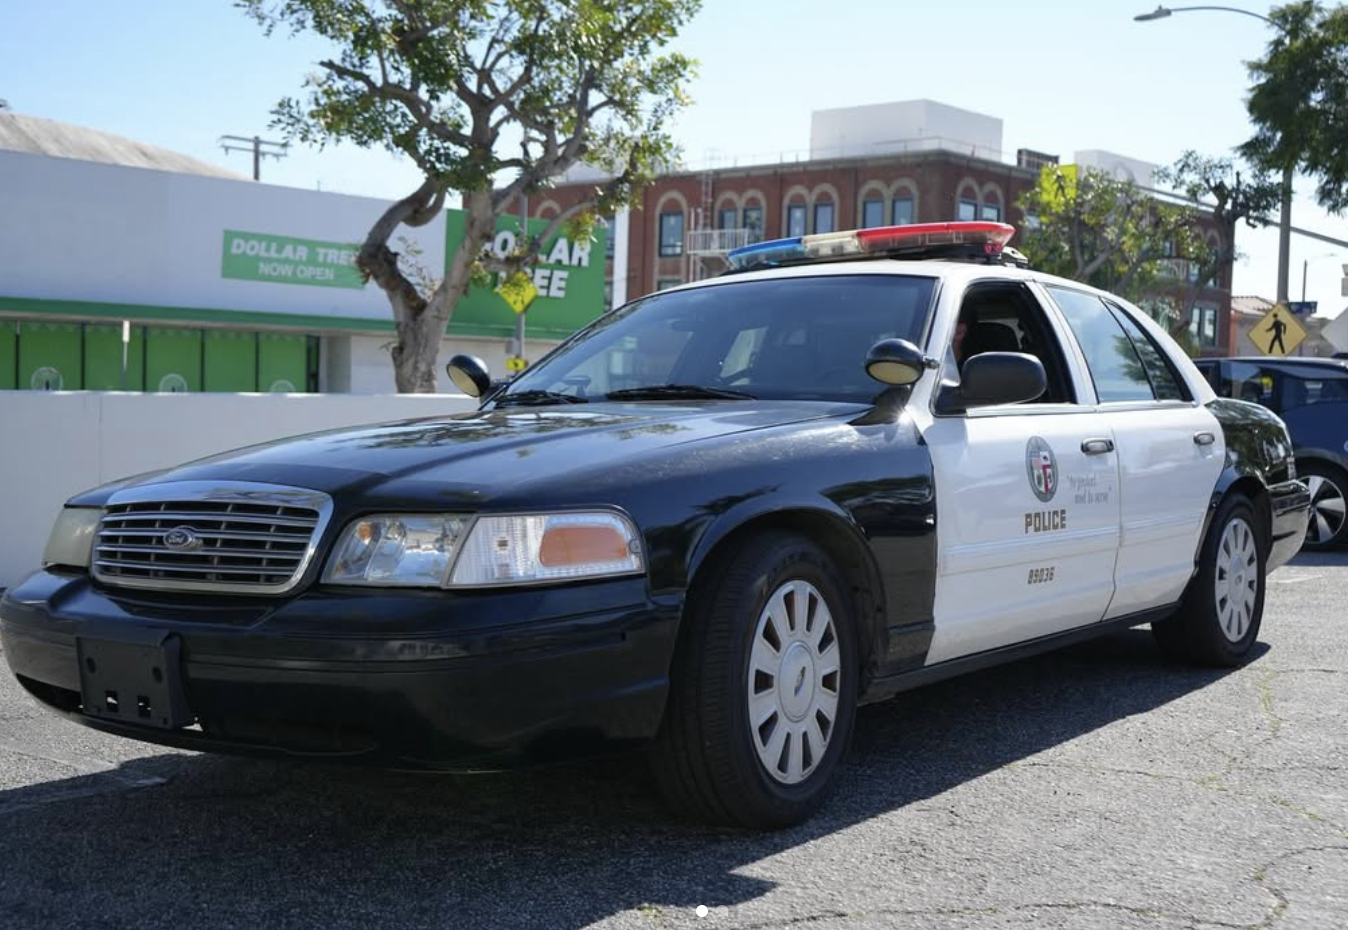
LAPD drops Flock license plate reader after systematic false positives
Los Angeles Police Department's decision to let its Flock automated license plate reader contract expire signals growing institutional skepticism toward computer vision systems deployed in law enforcement. The department's acknowledgment that the technology systematically flagged innocent vehicles as stolen, triggering unnecessary stops and surveillance, exposes a critical failure mode in real-world AI deployment: high false-positive rates in safety-critical contexts where human oversight proved insufficient. This outcome matters beyond policing because it demonstrates how algorithmic errors compound through organizational workflows, and it establishes precedent for municipal governments reconsidering vendor lock-in on surveillance infrastructure.69

Sutton launches Oak Lab to move beyond deep learning's efficiency limits
Richard Sutton, the Turing Award-winning pioneer of reinforcement learning, is launching Oak Lab to challenge the current deep learning paradigm. Sutton argues that contemporary methods are fundamentally limited in efficiency and capability, positioning continuous environmental learning as the path forward. This move signals growing skepticism among foundational AI researchers about scaling existing architectures, and could reshape how the field approaches agent development beyond supervised and fine-tuned models. The startup's focus on autonomous learning systems represents a potential inflection point for reinforcement learning's role in next-generation AI.85
Apple sues OpenAI over alleged hardware espionage during recruitment
Apple's lawsuit against OpenAI alleges systematic talent poaching and intellectual property theft, with claims that OpenAI recruiters solicited confidential hardware components and unreleased prototypes during job interviews. The case exposes competitive friction between hardware-focused and AI-native companies over talent acquisition practices and raises questions about information barriers during recruitment. For the AI industry, this signals escalating legal risk around hiring practices and sets a precedent for how companies must manage confidentiality during talent transitions, particularly as frontier labs compete for specialized engineering expertise.
Distributed backdoors bypass local LLM safety monitors
Researchers have identified a critical vulnerability in runtime monitoring systems that protect multi-agent LLM deployments. By distributing malicious payloads across multiple agents, attackers can evade local safety checks that individually flag each component as benign. The work formalizes this as an observability boundary problem, proving that monitors operating on isolated message streams cannot detect coordinated harm that emerges only when fragments are reassembled. This finding exposes a fundamental gap in current deployment safeguards for tool-using systems, forcing a rethinking of how safety infrastructure scales to distributed architectures.68

Nobel laureates and AI labs call for urgent economic preparation amid labor uncertainty
A coalition of 16 Nobel laureates and researchers from leading AI labs has issued a joint warning that policymakers face a narrowing window to prepare for AI's labor market disruption. The statement frames AI transformation as potentially more disruptive than industrialization but compressed into years rather than decades. The appeal carries weight from Google, OpenAI, and Anthropic signatories, yet the underlying research remains thin: existing labor studies show no measurable AI employment effects to date, and the statement itself lacks concrete policy proposals. This gap between urgency rhetoric and empirical evidence signals a critical moment where AI leadership is pushing for proactive governance before economic impacts become undeniable.73

Researchers build culturally-grounded moral reasoning for multilingual AI systems
Researchers tackle a critical gap in LLM deployment: moral reasoning systems trained and evaluated almost entirely in English fail to capture culturally distinct ethical frameworks across languages. This work introduces MCLASH, a culturally-grounded multilingual benchmark that moves beyond simple translation, and MET, a theory-informed inference method that grounds moral decisions in established ethical frameworks rather than English-centric heuristics. The contribution matters because as language models proliferate globally for high-stakes decisions, systems that flatten moral intuitions across cultures risk both misalignment and harm. This positions culturally-aware reasoning as infrastructure-level concern for responsible LLM deployment.62
Neural actuator model cuts sim-to-real error on low-cost robots
Sim-to-real transfer remains a critical bottleneck in robot learning, and actuator modeling is where theory meets friction. NeuralActuator addresses a concrete failure mode: the linear torque model breaks down on cheap servos due to hysteresis, backlash, and thermal lag. By learning a neural surrogate that jointly predicts effort, external forces, and motor health, the work reduces a major source of policy brittleness without requiring force sensors. The accompanying Neural Actuation Dataset signals a shift toward standardized benchmarks for actuator fidelity, likely to influence how roboticists validate sim-to-real pipelines going forward.62
Anthropic launches rupee pricing for Claude in India
Anthropic is rolling out rupee-denominated pricing for Claude in India, signaling a strategic pivot toward emerging markets where currency conversion friction has historically limited adoption. This localization move reflects the AI industry's broader shift from US-centric monetization toward regional pricing strategies that account for purchasing power parity. For Claude, India represents a massive untapped user base, and removing the dollar barrier could accelerate both consumer and enterprise adoption in a market where local payment methods and local pricing psychology matter significantly. The move also positions Anthropic competitively against OpenAI and Google, which have pursued similar localization tactics.
RAGU separates graph extraction from consolidation to reduce RAG noise
RAGU decouples knowledge graph construction into extraction and consolidation stages, replacing single-pass noisy pipelines with multi-step refinement including deduplication, summarization, and community detection. The system's core insight challenges scaling assumptions: language comprehension and extraction skills plateau with model size, unlike factual knowledge. This motivated Meno-Lite-0.1, a 7B parameter extractor that outperforms larger alternatives by optimizing for linguistic reasoning rather than memorization. The approach signals a shift toward task-specific model sizing in RAG systems, where downstream performance depends less on parameter count than on targeted capability alignment.62

Hiring becomes AI battleground as candidates and employers deploy detection tools
Technical hiring has become a bidirectional AI deployment zone. Candidates now use AI assistants to generate real-time interview responses, forcing employers to deploy detection systems that identify AI-assisted answers. This escalation reflects deeper labor-market pressures: widespread tech layoffs have intensified competition, making AI-augmented performance tempting for job seekers, while companies face mounting pressure to filter for genuine capability. The dynamic exposes a fundamental tension in AI adoption: as the technology becomes ubiquitous, traditional gatekeeping mechanisms break down, and both sides race to maintain informational asymmetry. Industry observers predict human judgment will ultimately dominate hiring decisions, but the arms race signals how thoroughly AI is reshaping workplace credentialing.
Spectral regularization unlocks control over neural network grokking timing
Researchers have identified dimensionality collapse as a consistent precursor to grokking, the puzzling phenomenon where neural networks suddenly generalize after extended training on memorized data. The team proposes Geometric Dimensionality Regularization, a spectral regularizer that controls representation geometry to influence when and how grokking emerges. Validated across modular arithmetic and permutation tasks, this work moves grokking from an observed curiosity toward a controllable training dynamic. The ability to steer delayed generalization has implications for training efficiency and our understanding of how networks transition from memorization to abstraction, a foundational question in deep learning.62
Transformer learns Alzheimer's risk without filling missing clinical data
Researchers introduce NITROGEN, a transformer architecture that sidesteps traditional imputation for handling incomplete clinical data in Alzheimer's prediction. Rather than filling missing values and introducing bias, the model uses masked and intersample attention to learn directly from sparse multimodal records. This approach addresses a fundamental pain point in healthcare AI: real-world datasets are messy, heterogeneous, and incomplete, yet existing methods either distort relationships or produce overconfident predictions. Trained on ADNI's 7,858 scans, NITROGEN demonstrates how architectural choices can replace preprocessing steps entirely, potentially reshaping how medical AI handles incomplete data across diagnostic domains.62

Lesioned language models reproduce stroke aphasia naming errors
Researchers demonstrated that systematically damaging multimodal language models can reproduce the specific error patterns observed in stroke-induced aphasia, validating LLMs as computational proxies for human language pathology. By applying targeted perturbations to LLaVA 1.6 across different layers and noise levels, the team successfully replicated six of seven error categories from the Philadelphia Naming Test across 278 patients with aphasia. This work bridges neuroscience and AI, suggesting that language model internals may reflect principles of human linguistic organization and opening pathways for clinical simulation, diagnostic modeling, and interpretability research grounded in real neurological data.62