Earlier stories
Every published Modelwire story, newest first. The homepage leads with the weekly overview and this week’s hottest; this is the full collection.

OpenAI embeds web app deployment directly into ChatGPT
OpenAI has integrated web app development directly into ChatGPT, collapsing the gap between natural language specification and deployed software. Users can now iterate on applications through conversational feedback, with hosting and storage provisioned automatically. This represents a significant shift in the developer experience layer: the friction of context-switching between chat and IDE, managing infrastructure, and handling deployment vanishes. For the AI product ecosystem, this signals OpenAI's bet that LLM-driven code generation has matured enough to anchor a primary user workflow. The move compresses the path from idea to live application, potentially reshaping how non-technical and technical users alike prototype and ship.
Major publishers sue Google over unlicensed AI training data
Major publishers including Hachette, Cengage, and Elsevier are suing Google over unauthorized use of copyrighted material in AI model training, escalating a pattern of legal challenges that threatens the data acquisition model underpinning large language model development. This case signals publishers' willingness to litigate rather than negotiate licensing terms, potentially forcing AI labs to either secure explicit permissions, pay licensing fees, or restrict training data sources. The outcome could reshape how frontier models are built and trained.
LLM agents waste compute by over-scanning context, new framework cuts redundancy
Researchers identify a critical inefficiency in LLM agent workflows: agents routinely over-scan context and re-examine already-processed information, inflating computational cost without improving outcomes. The paper introduces task-aware execution-scope estimation, formalizing the Agent Cognitive Redundancy Ratio and proposing E3, a framework that estimates task difficulty upfront, executes a minimal viable path, and expands scope only when verification fails. This addresses a practical pain point for production AI systems where token budgets and latency matter, shifting agent design from maximum-context-first to minimum-sufficient reasoning.62
Video diffusion models struggle with causal chains in physics
Video diffusion models fail to track causal chains in physical systems, a limitation researchers term the seriality gap. When predicting multi-ball collisions, standard bidirectional denoisers degrade sharply as interaction sequences lengthen, independent of video duration. The root cause is architectural: models lack sufficient serial computation depth to resolve dependent events. Autoregressive and deep architectures recover performance, suggesting that generative video systems need fundamentally different inductive biases to handle physics-like reasoning. This finding reshapes how practitioners should design video models for tasks requiring temporal causality.62
TerraZero reaches 1.3M steps per second in procedural driving simulation
TerraZero addresses a critical bottleneck in autonomous driving research: simulators that are simultaneously fast enough for large-scale RL training, faithful to real-world geometry, and diverse enough to capture safety-critical edge cases. By sustaining 1.3M agent-steps per second on commodity GPU hardware while modeling heterogeneous traffic agents and enforcing traffic rules, the system decouples simulation speed from fidelity trade-offs that have constrained prior work. This matters because self-play training at scale requires orders of magnitude more interaction than logged data provides, and procedural generation of map-grounded scenarios could accelerate the path to robust driving policies without relying on expensive real-world collection.62
Information theory reveals the cost of watermarking generative models
Researchers have formalized watermarking for generative models through information theory, establishing a quantitative framework for what forensic tasks cost in token length. The work reveals a hierarchy: detection requires only distributional distance, while attribution and payload extraction demand information mass accumulated across tokens, and localization depends on how that mass distributes temporally. This theoretical foundation matters because it clarifies the fundamental tradeoffs between watermark robustness, capacity, and resilience to editing, directly informing how AI labs can design provenance systems that survive real-world deployment and tampering.62
Hassabis proposes independent AI standards body modeled on financial regulation
Demis Hassabis is pushing for a third-party standards body to evaluate frontier AI systems before deployment, drawing parallels to financial-sector oversight. The proposal signals growing pressure within the AI establishment to formalize safety vetting outside individual company control, potentially reshaping how labs coordinate on release practices. This reflects a shift in frontier-lab thinking: as capabilities accelerate, self-governance appears insufficient to key stakeholders. If adopted, such a body could become a bottleneck or legitimacy layer for major model releases, affecting competitive timelines and raising questions about who sits on the board and what standards actually stick.
Anthropic launches free Claude tier for teachers with student data training ban
Anthropic is carving out the education sector as a distinct market by launching Claude for Teachers, a free tier targeting verified K-12 educators in the US. The move pairs product accessibility with a contractual commitment: student interactions will not feed model training pipelines. This signals a strategic pivot toward institutional trust and regulatory defensibility as AI vendors face mounting scrutiny over data practices in sensitive domains. For educators and school IT leaders, the no-training pledge removes a key friction point in adoption. For competitors, it raises the bar on data governance commitments in regulated verticals.73
Meta sued over AI-driven layoff targeting of employees on leave
Meta faces litigation from 26 former employees alleging the company deployed internal AI systems to systematically identify and terminate workers on leave, using performance metrics as the targeting mechanism. The lawsuit exposes a critical tension in enterprise AI deployment: algorithmic decision-making in workforce management can amplify existing biases and create legal exposure when applied to protected categories. This case signals growing scrutiny of how large tech firms operationalize AI for high-stakes HR decisions, potentially reshaping corporate governance around algorithmic transparency and human oversight in personnel actions.
LLM benchmark stability masks per-example prediction instability
A new study reveals that state-of-the-art LLMs mask fragility behind stable aggregate benchmarks. While overall accuracy remains unchanged when task-irrelevant context is prepended to questions, individual predictions flip unpredictably on a subset of examples, even when triggered by meaningless character sequences. This instability persists across multiple model families and datasets, suggesting that current evaluation metrics fail to capture real-world brittleness in context-rich deployments. The finding challenges assumptions about model robustness and has direct implications for production systems relying on benchmark scores as reliability proxies.62
Oracle embeds agentic AI into Fusion developer platform
Oracle is expanding its agentic AI platform to serve developers building on its Fusion application suite, signaling a strategic pivot toward enterprise automation. The move reflects Oracle's broader effort to embed autonomous agent capabilities across its cloud infrastructure, competing directly with Salesforce, SAP, and hyperscalers offering similar agent-native development environments. For enterprise software vendors, this represents a critical inflection point: applications that don't natively support agentic workflows risk obsolescence as customers demand autonomous task execution. Oracle's focus on its installed base of Fusion developers suggests the company sees agent-driven process automation as the next major revenue lever in enterprise software.61
Taiwan chipmaker scales photonics output for AI data centers
Taiwan's second-largest chipmaker is ramping photonics production capacity in response to surging AI infrastructure demand, signaling a strategic pivot toward optical interconnect solutions for data centers. This move reflects the industry's recognition that traditional silicon alone cannot sustain the bandwidth and power efficiency requirements of next-generation AI workloads. The expansion underscores a critical supply-chain shift: as model training scales, chipmakers are diversifying beyond conventional processors into photonic components that reduce latency and energy consumption in AI clusters. This development matters for infrastructure investors and AI practitioners tracking the hardware bottlenecks constraining model scaling.61

DeepSeek returns to fundraising after $7 billion close to fund datacenters
DeepSeek's rapid return to fundraising reveals the capital intensity underlying its competitive pricing strategy in frontier AI. The Chinese lab closed a $7 billion round but now seeks additional capital specifically for proprietary datacenter infrastructure and chip procurement, signaling that aggressive model pricing requires sustained hardware investment to remain viable. This pattern underscores a structural shift in AI competition: sustained capability gains and low-cost inference depend on vertical integration of compute, not just model development. For the industry, DeepSeek's capital needs validate that competing on price while maintaining frontier performance demands infrastructure parity with incumbents.85
Meta predicts token budgets will become standard engineering cost controls
Meta's leadership is signaling that enterprise AI spending will soon face structural constraints, mirroring how companies budget for engineering headcount. Mosseri's framing suggests token consumption is becoming a material cost center that boards and finance teams will scrutinize, forcing engineering organizations to make trade-offs between model capability, inference volume, and tool adoption. This reflects a maturing market where AI infrastructure costs are no longer treated as experimental overhead but as a line item requiring governance, potentially reshaping how teams prioritize between in-house models, third-party APIs, and cached inference strategies.
Google Search fills image gaps with generative AI synthesis
Google is embedding generative image capabilities directly into Search, deploying its Nano Banana 2 Lite model to synthesize visuals when web results fall short. This marks a strategic shift in how search engines handle information gaps, moving beyond retrieval toward on-demand content synthesis. The rollout signals Google's bet that generative AI can improve user experience when traditional indexing fails, while raising questions about authenticity signals and user trust in algorithmically-created imagery within search results.73

YouTube and X direct users to nonconsensual deepfake services
Generative AI tools designed to create nonconsensual sexual imagery have found a distribution channel through mainstream social platforms. YouTube and X are surfacing links to deepfake services that monetize abuse at minimal cost per image, revealing a critical gap between platform moderation systems and the downstream harms enabled by synthetic media technology. This exposes how AI infrastructure built for legitimate use can be weaponized at scale when platforms lack enforcement mechanisms, raising urgent questions about liability and the real-world consequences of uncontrolled generative capabilities.76

Kuszmar documents cross-model safety bypasses affecting major LLMs
Researcher Dave Kuszmar has documented systemic vulnerabilities across major LLMs that allow attackers to extract dangerous information by circumventing safety guardrails. The exploits appear to work on nearly all leading models, signaling a fundamental gap in current safety architectures rather than isolated flaws. Kuszmar's findings underscore that deployment velocity has outpaced defensive research, and he advocates for industry-wide transparency, slower rollout timelines, and coordinated safety investment before these systems become more deeply embedded in critical infrastructure.
LatentFlow enables training-free conditioning for stochastic processes
LatentFlow addresses a fundamental bottleneck in probabilistic modeling: conditioning stochastic processes on complex, real-world observations. The framework sidesteps the need for model-specific inference schemes by reformulating process conditioning as latent-space sampling through a deterministic transformation, eliminating both neural approximations and training overhead. This approach expands the practical applicability of stochastic models across domains requiring non-linear observations, non-Gaussian likelihoods, and global constraints, potentially reshaping how practitioners handle uncertainty quantification and inverse problems in scientific computing and machine learning.62
Spotify embeds conversational AI into music discovery and playback
Spotify is embedding conversational AI into its core discovery and playback experience, letting Premium users query music, podcasts, and audiobooks through natural language rather than search or browse. This represents a strategic shift in how streaming platforms compete: moving from algorithmic recommendation feeds to agentic interfaces that reduce friction between intent and consumption. The rollout signals that major consumer platforms now view LLM-powered chat as table stakes for engagement, not a novelty feature. For the AI landscape, it validates the commercial viability of lightweight conversational agents embedded in existing workflows, potentially pressuring competitors to follow suit.
LLM judges overrate wrong answers without reference data
A new study reveals a critical flaw in using LLMs as evaluation judges for open-ended tasks: without reference answers, these models systematically overrate incorrect responses. The research combines calibration testing with sensitivity analysis across three languages to show that judge performance degrades significantly when ground truth is absent, and improves only when reference answers are explicitly provided in prompts. This finding directly challenges the growing practice of using LLM judges as a scalable alternative to human evaluation, suggesting that practitioners relying on reference-free assessment may be getting inflated quality signals that mask actual model performance gaps.62
New benchmark exposes LLM failures in correcting medical misconceptions
Researchers have identified a critical gap in how LLMs are evaluated for medical safety: current benchmarks ignore misconception handling across multi-turn conversations. The new ThReadMed-QA dataset of 2,437 patient-physician dialogue threads tests whether models can detect false assumptions embedded in questions and correct them over time, rather than simply answering queries as posed. This matters because real medical communication requires active belief correction, not passive response generation. The work exposes a blind spot in production LLM deployment for healthcare, where persistent or evolving misconceptions could compound harm across a conversation.62
New York blocks new data center permits amid AI infrastructure strain
New York's moratorium on large data center approvals marks the first state-level pushback against AI infrastructure expansion, signaling a shift in how jurisdictions balance computational demand against resource constraints. Governor Hochul's move reflects growing tension between the AI industry's power and water needs and local governance priorities. This precedent could reshape where companies build next-generation compute capacity, forcing tech firms to negotiate more carefully with state regulators or relocate projects to friendlier jurisdictions. The decision underscores that AI scaling now faces infrastructure and political friction beyond technical capability.
Researchers isolate and remove bias from transformer attention heads at inference time
Researchers have developed ROBIN, a method to identify and surgically remove bias from transformer models at inference time by targeting specific attention heads. Rather than retraining entire models or filtering inputs and outputs, the technique uses sensitivity analysis to pinpoint which heads drive unfair behavior, then strips bias-related subspaces from their outputs. Early results across four models show measurable fairness improvements on benchmarks like WinoBias while maintaining language modeling performance. This represents a shift toward interpretable, surgical model repair that could make deployed LLMs easier to debug and patch without full retraining cycles.62
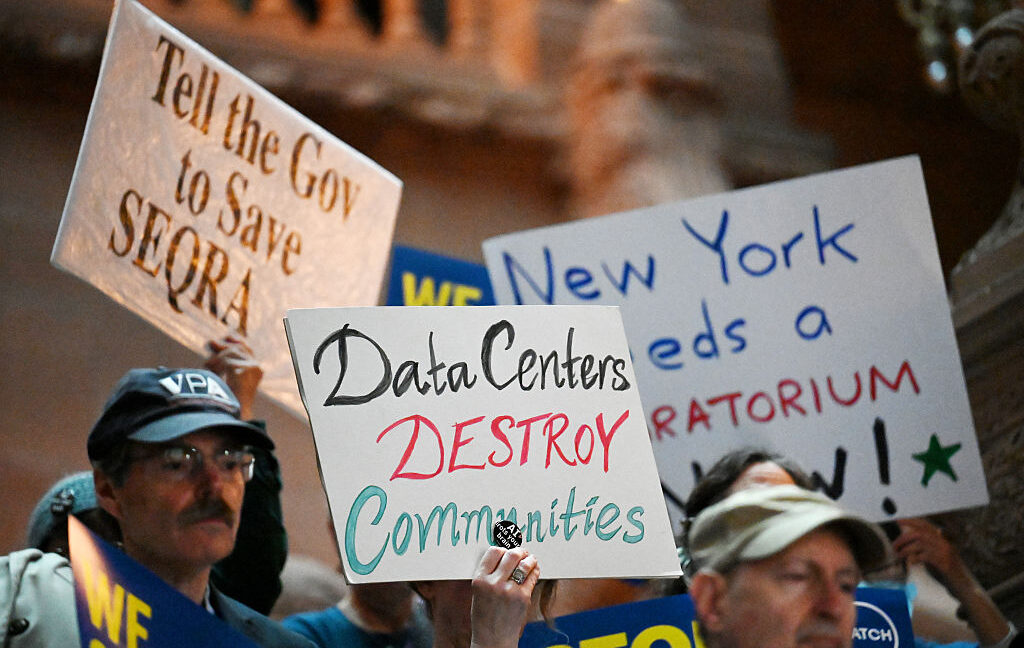
New York halts data center expansion, testing state-level AI infrastructure limits
New York's one-year moratorium on data center construction signals a critical inflection point for AI infrastructure policy in the US. The ban targets the energy-intensive compute facilities underpinning large language model training and deployment, directly constraining capacity for both established players and startups. If other states adopt similar restrictions, the fragmentation could reshape where AI companies build infrastructure, potentially accelerating investment in regions with lighter regulatory touch or forcing consolidation around existing facilities. This move reflects growing tension between AI scaling demands and state-level concerns over power grid strain and environmental impact.
Anonymizing entities during pretraining reduces parametric recall in language models
Researchers propose a training paradigm that deliberately weakens language models' ability to retrieve facts from their parameters by anonymizing named entities during pretraining. The approach, called Knowledge-Less Language Models, trades raw factual recall for improved performance on context-dependent reasoning tasks. This work addresses a fundamental tension in LLM design: models trained on broad internet data absorb outdated or conflicting information that can override provided evidence. The finding matters for practitioners building retrieval-augmented systems and for understanding how training signals shape model behavior beyond raw capability metrics.62
Reflection AI locks $1B compute deal with Nebius
Reflection AI, a 2024-founded startup building open-source AI systems, has secured $1 billion in compute access from Nebius, a cloud infrastructure provider. This deal signals growing competition in the compute supply chain as emerging AI labs seek alternatives to hyperscaler dominance. For a young company, securing dedicated infrastructure at scale is a critical moat; the partnership suggests Nebius is positioning itself as a compute backbone for the next wave of AI builders outside the OpenAI/Google/Meta ecosystem. The arrangement reflects broader market fragmentation as demand for training capacity outpaces traditional cloud providers' willingness to serve open-source competitors.
Hugging Face CEO: enterprises choosing open models over frontier systems
The competitive center of gravity in AI infrastructure may be shifting from cutting-edge model development toward production-grade open alternatives. Hugging Face leadership argues that enterprises are increasingly adopting open models over proprietary frontier systems, driven by total cost of ownership, operational control, and vendor independence. This trend challenges the assumption that capability leadership automatically translates to market dominance, suggesting the real value capture may lie in deployment efficiency and customization rather than raw model performance. For practitioners and infrastructure investors, this signals a maturing market where accessibility and ownership trump novelty.
Meta's Louisiana supercluster reaches $50 billion as compute arms race intensifies
Meta's Louisiana AI supercluster project has ballooned to $50 billion, reflecting the capital intensity now required to compete in frontier model development. This scale of infrastructure investment signals a structural shift in AI economics: compute capacity has become a primary competitive moat, and only the largest tech firms can sustain the power, cooling, and real-estate costs at this magnitude. The project underscores how AI leadership is increasingly determined by datacenter buildout velocity rather than algorithmic innovation alone, reshaping the competitive landscape for smaller players and raising questions about energy and geopolitical concentration.76
Language models converge on identical answers far more than chance predicts
Researchers deployed a minimal but revealing benchmark across 44 language models, asking each to generate single words from open-ended categories. The results expose a striking monoculture: when faced with infinite valid answers, models converge on identical choices at rates far above chance, with 'serendipity' appearing in 41% of responses to an unconstrained word-pick prompt. This One-Word Census uses only 31 prompts and costs roughly a dollar per model to run, yet surfaces a fundamental property of LLM training dynamics. The finding matters because it quantifies how training data and architectural similarities collapse the decision space in ways that feel random to users but are deeply deterministic across the industry, raising questions about diversity, predictability, and whether current scaling approaches inadvertently homogenize model behavior.62