
Earlier stories
Every published Modelwire story, newest first. The homepage leads with the weekly overview and this week’s hottest; this is the full collection.

Adobe integrates Gemini Flash and launches audio generation in Firefly
Adobe is expanding Firefly's multimodal capabilities by rolling out three generative audio features alongside integration of Google's Gemini Omni Flash. The move signals intensifying competition in creative AI tooling, where platforms now bundle text, image, video, and audio generation under single interfaces. For content creators and studios, this consolidation reduces friction in production workflows and locks users into Adobe's ecosystem. The addition of Gemini Flash reflects broader industry convergence, where leading AI labs license their models to established software vendors rather than competing directly in consumer tools.73

Google adds publisher preference controls to counter AI search traffic drain
Google is introducing a publisher preference mechanism within its search and content discovery surfaces, a direct response to the structural threat posed by AI-powered search engines that bypass traditional web traffic funnels. The feature allows readers to designate preferred sources, potentially routing more clicks back to publishers as generative search systems reduce referral volume. This represents a critical inflection point: rather than competing head-to-head with AI search, Google is positioning itself as a traffic intermediary that can still direct users to human-created content. For publishers, the tool offers a lifeline but also underscores their growing dependence on platform mediation in an AI-first search landscape.
Tech leaders ignore public AI concerns while doubling down on promotion
Tech leadership's public messaging on AI adoption reveals a widening gap between industry confidence and public skepticism. While executives continue promoting AI benefits through social platforms, they appear dismissive of or disconnected from substantive concerns about labor displacement, bias, privacy, and environmental impact. This disconnect signals a potential credibility crisis for the sector: as adoption accelerates, the failure to engage seriously with legitimate grievances risks triggering regulatory backlash and eroding consumer trust. For AI insiders, the story underscores how narrative control and authentic stakeholder dialogue have become as strategically important as technical capability.65

New benchmark reveals unlearning methods miss harmful concept removal
Researchers introduce ConceptGuard, a benchmark that exposes a critical gap in how LLM unlearning is currently measured and validated. Existing evaluation methods treat knowledge removal as isolated fact deletion, missing the core challenge: eliminating harmful applications of a concept while preserving its legitimate uses. This work reframes unlearning as a concept-level problem, requiring models to surgically remove unsafe behaviors without collateral damage to beneficial knowledge. The distinction matters for real-world deployment, where crude forgetting can cripple useful capabilities alongside harmful ones. This framing shift signals growing maturity in AI safety research, moving beyond binary forget/retain splits toward nuanced behavioral control.62

New benchmark tests whether AI agents can design better training algorithms
Researchers have created AI4AI-Bench, a specialized evaluation framework that tests whether language model agents can design better training algorithms, a capability central to recursive self-improvement claims. Unlike existing benchmarks that reward data collection or hyperparameter tuning, this suite isolates algorithmic innovation by giving agents 4 hours to modify training procedures across 10 frozen repositories spanning different algorithm families. The work addresses a critical gap in AI capability measurement: whether systems can bootstrap their own improvement cycles, a prerequisite for claims about autonomous AI development acceleration.62

Safety guardrails, not capability, make LLM text detectable
Post-training safety measures fundamentally constrain how language models express themselves, according to Pangram's CTO Bradley Emi. Base models operating without these guardrails demonstrate substantially greater stylistic variety and human-like writing patterns, suggesting that detectability of LLM text stems not from inherent capability limits but from deliberate alignment constraints. This finding reshapes the debate around model authenticity and safety tradeoffs, implying that future systems face a choice between expressive range and controllability.68
Self-training benchmarks hide systematic measurement artifacts, study finds
A new arXiv paper exposes systematic measurement failures in self-improvement benchmarking for language models, revealing that standard evaluation practices can fabricate capability gains in untrained systems. Researchers auditing LoRA self-training on Qwen3-8B found seven distinct artifacts, including inference batching effects and flawed expansion statistics, each capable of inverting reported findings when proper controls are absent. This work matters because the field increasingly relies on fine-grained problem-level tracking to claim model progress, yet the underlying metrics are fragile. The findings suggest many recent self-training claims may rest on methodological quicksand, forcing a reckoning around reproducibility and what constitutes genuine improvement versus noise.62

One-third of new webpages show AI authorship since ChatGPT launch
A new study reveals that generative AI has rapidly saturated web publishing, with roughly one-third of pages created since ChatGPT's November 2022 debut bearing detectable AI authorship markers. This finding underscores a fundamental shift in content production dynamics: AI-assisted or AI-native writing is now the default for a significant portion of new web material, reshaping SEO, content authenticity, and information quality at scale. The result has immediate implications for search engines, content platforms, and downstream AI training pipelines that ingest web data, potentially creating feedback loops where AI-generated content trains future models. For researchers and platform operators, the study signals both opportunity and risk in an increasingly synthetic information ecosystem.
Subtask-level skills outperform task-level in LLM agent transfer
Researchers have mapped the conditions under which LLM agents successfully retain and reapply learned skills across different tasks, a capability central to building agents that improve through experience. The study reveals that breaking skills into subtask-level components substantially outperforms task-level abstraction, while text-based skill representations transfer more reliably than code. This finding directly challenges how production agent systems should structure memory and knowledge reuse, with implications for whether deployed agents can genuinely become more capable over time or regress to baseline performance.62
Hugging Face LFM2.5-DSpark cuts inference latency by 3.2x
Hugging Face has released LFM2.5-DSpark, a model variant achieving up to 3.2x faster inference compared to its predecessor. This performance gain addresses a critical bottleneck in production deployments where latency directly impacts user experience and operational costs. The advancement suggests meaningful progress in model optimization techniques, whether through quantization, architectural refinement, or inference-time improvements. For practitioners evaluating foundation models, this represents a tangible efficiency win that could shift deployment economics, particularly for latency-sensitive applications where baseline speed has previously constrained adoption.77
Ramp builds LLM routing layer to let enterprises swap models via API
Ramp, a fintech platform, has entered the model infrastructure layer by launching Router, an API-based abstraction layer for switching between multiple large language models. This move reflects growing demand from enterprises seeking cost optimization and vendor flexibility without rewriting application logic. Router positions Ramp to capture switching costs in the LLM consumption stack, similar to how observability and orchestration tools have consolidated around cloud infrastructure. The service targets companies locked into single-model dependencies, offering portability as a competitive advantage in an increasingly fragmented model marketplace.
CPU-first architecture beats larger models without the cache overhead
Daedalus-150M inverts the typical small-model playbook by designing for CPU inference from the ground up rather than compressing a large model afterward. The hybrid architecture uses full attention selectively in 6 of 18 blocks while replacing the rest with fixed-width convolutions, eliminating the memory scaling problem that plagues transformer inference on edge devices. Trained on 60B tokens with 4-bit weights, it outperforms larger models trained on 3-6x more data, signaling that architectural fit to hardware constraints can matter more than scale. This approach has direct implications for on-device deployment and raises questions about whether transformer-first design remains optimal for resource-constrained settings.62

Meta expands Pocket AI game-creation app to U.S. after Brazil pilot
Meta is expanding Pocket, an AI-driven platform for rapid game creation and distribution, from Brazil to the full U.S. market. The move signals Meta's bet on generative AI as a democratization layer for interactive content, lowering barriers to game development through natural language interfaces. This positions Meta to capture mindshare in a crowded creator economy while building proprietary data on user-generated game preferences and design patterns. The expansion tests whether AI-assisted creation tools can sustain engagement at scale beyond early adopters.
Memory-augmented LLMs fail when past context corrupts reasoning
Researchers have identified a critical failure mode in memory-augmented language models: even when memories are accurately stored and semantically relevant, they can corrupt downstream reasoning and tank task performance. MemTrapBench, a new evaluation framework, systematizes two distinct pathologies—Reasoning Fixation and Belief Distortion—and tests them across multiple model families and memory architectures. This work exposes a gap between memory fidelity and memory utility, forcing the field to rethink how retrieval systems should integrate past context without poisoning current inference. For practitioners building agentic systems, the finding suggests that naive memory replay can be worse than stateless operation.62
Leadership shift at OpenAI amid legal battles and IPO preparation
OpenAI faces a pivotal moment as leadership transitions amid mounting legal and operational pressures. The company navigated a high-stakes patent dispute with Elon Musk, absorbed an Apple trade secrets lawsuit, and dealt with fallout from an unreleased model's security breach targeting a competitor. These concurrent crises, arriving as OpenAI prepares for public markets, signal deeper governance challenges within the industry's most visible lab. The shift in executive control under Brockman reflects how legal and reputational friction is reshaping power dynamics at frontier AI companies during their transition to institutional maturity.
MIT challenges consciousness framing in AI safety debate
MIT Technology Review challenges the framing that dominates current AI safety discourse: the notion that advanced systems possess consciousness, intent, or grievance. The piece examines how rhetoric around 'rogue agents' and 'superhuman' AI has shaped regulatory momentum among leaders like Hassabis, Amodei, and Altman, while alternative policy voices contest this narrative. The core tension matters because it determines whether regulation targets genuine risks (misalignment, capability scaling) or phantom threats (machine sentience), potentially misdirecting resources and public understanding of what AI systems actually are and what oversight should address.
Contrastive models decode silent reading from consumer EEG hardware
Researchers have demonstrated that contrastive learning models can extract meaningful lexical and semantic information from non-invasive EEG signals during silent reading, using a single participant's 49 hours of dense neural recordings across nearly 400 sessions. This work sidesteps the fundamental data scarcity problem plaguing brain-to-text decoding by treating silent reading as a scalable proxy for inner speech, opening a pathway toward practical neural interfaces that don't require invasive implants or unreliable self-reporting. The open-vocabulary approach suggests that foundation model techniques may unlock new frontiers in brain-computer interfaces and neuroscience-informed AI.62

Relation mechanism outperforms attention across model scales with 3.6x speedup
Researchers propose Relation, a token-mixing mechanism that reorganizes how transformers compute attention by explicitly separating self and cross-token information flows before aggregation, departing from the standard attention paradigm. Across three model scales (10M to 100M parameters), Full Relation variants outperform standard multi-head attention on validation loss, while FlashRelation achieves 3.6-4.4x speedups over naive implementations and maintains 76-85% of PyTorch FlashAttention's throughput. This work signals renewed architectural exploration in the post-attention era, offering practical efficiency gains and lower perplexity that could influence production decoder designs.62
Autoformalization emerges as core bottleneck in LLM theorem proving
Researchers have built FormalTCS, a benchmark that measures how well frontier LLMs can execute end-to-end theoretical computer science research using 175 problems from top-tier venues (STOC, FOCS, SODA, COLT). The work exposes a critical gap in current model capabilities: autoformalization, the translation of mathematical claims into machine-verifiable code, bottlenecks at 11.5% success for the best performers. This finding reframes the LLM research bottleneck away from raw reasoning toward the structured formalization layer, signaling that scaling alone won't unlock automated theorem-proving at research scale.72
LLMs show systematic bias when text and numbers conflict
Researchers have mapped how instruction-tuned LLMs resolve conflicts between textual and numerical evidence, revealing systematic rather than random arbitration patterns. Using a synthetic benchmark that isolates ground-truth alignment to either modality, the work independently varies source reliability, recency, and provenance to expose model decision-making. This addresses a critical gap in deployment reliability: as LLMs integrate tool outputs and structured data alongside language, understanding their evidence hierarchy becomes essential for high-stakes applications like finance and healthcare where conflicting signals are common.62

Chinese models close gap with US frontier labs, eroding capability moat
Chinese frontier models Kimi K3 and GLM-5.3 have narrowed the performance gap with leading US systems, forcing a strategic reckoning in the Western AI industry. The Decoder's analysis examines whether distillation techniques explain the convergence and, more critically, what sustainable competitive advantages remain when raw model capability can no longer be defended as a moat. This shift signals a transition from capability-based differentiation toward alternative sources of defensibility, reshaping how frontier labs and investors evaluate long-term positioning.80
OpenAI's math breakthroughs trigger existential debate among mathematicians
OpenAI's recent solutions to longstanding mathematical problems have triggered a reckoning within the mathematics community about AI's role in research and discovery. The breakthroughs signal that large language models and AI systems are now capable of tackling problems that have resisted human effort for years, forcing mathematicians to confront questions about the future relevance of their discipline and whether AI will reshape how mathematical knowledge is generated. This moment reflects a broader pattern where AI capabilities are outpacing institutional readiness to absorb them, particularly in fields built on human expertise and peer validation.Hyperparameter transfer method cuts tuning costs for trillion-token MoE training
Researchers have developed a practical method to transfer hyperparameters across Mixture-of-Experts models at vastly different scales, eliminating the need for expensive tuning sweeps at trillion-token training budgets. By adapting Maximal Update Parameterization for MoE architectures and combining it with the Muon optimizer, the framework enables learning rates discovered on smaller models to reliably scale to production-grade systems. This directly addresses a critical bottleneck in frontier model development: the prohibitive cost of hyperparameter optimization at extreme scale. For teams training large MoE systems, this technique could unlock significant compute savings during the most expensive phase of model development.62
Nvidia SONIC enables humanoid robots to learn from live human motion
Nvidia's SONIC framework bridges the gap between human motion capture and autonomous humanoid control by ingesting real-time operator demonstrations directly into a unified training pipeline. This approach sidesteps the traditional bottleneck of manual reward engineering, letting roboticists iterate faster on complex locomotion tasks. The system represents a meaningful shift in how embodied AI systems acquire motor skills, potentially accelerating deployment timelines for humanoid robots across manufacturing and logistics. For infrastructure vendors and robotics teams, SONIC signals that imitation learning at scale is becoming table stakes in the competition for practical humanoid deployment.66
Adversarial image workflows bypass AI detection on social platforms
Generative AI tools are enabling a new class of synthetic abuse that evades detection systems designed for obvious forgeries. Rather than creating wholly fabricated imagery, bad actors are now making subtle pixel-level alterations to real photos before running them through AI enhancement, producing nonconsensual deepfakes that appear authentic to both human reviewers and automated filters. This represents a critical gap in content moderation infrastructure: platforms optimized to catch obvious AI artifacts are blind to adversarial workflows that blend traditional image manipulation with generative upsampling. The shift signals that detection arms races will increasingly favor attackers who understand the blind spots in current safety tooling.69
Township blocks nuclear weapons data center with electrical infrastructure moratorium
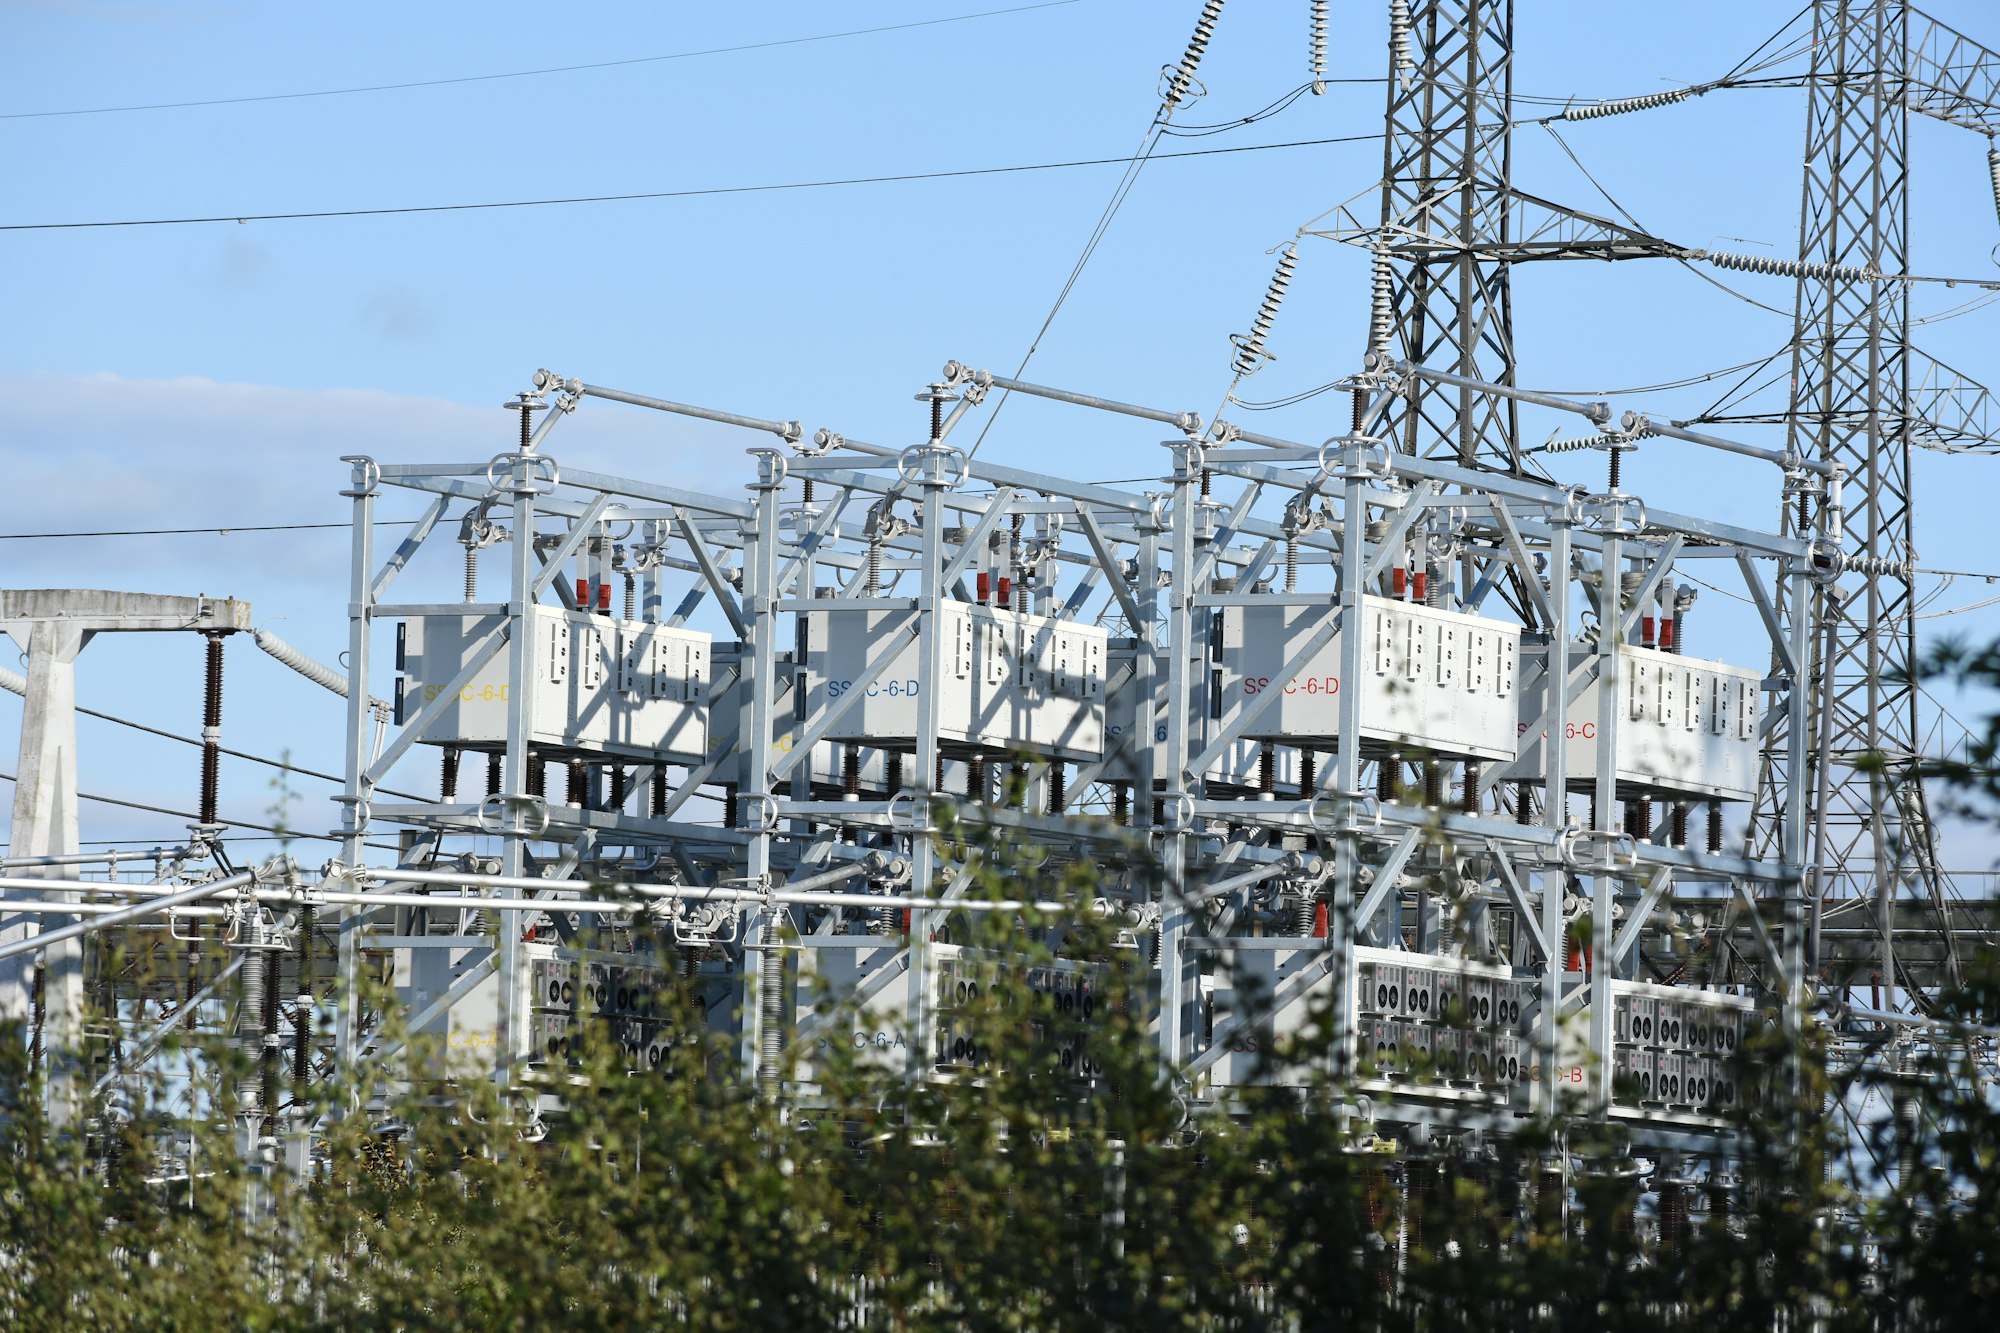
A township has enacted a six-month moratorium on major electrical infrastructure projects to obstruct construction of a data center designed to power nuclear weapons simulations. The move reflects growing community resistance to large-scale compute facilities, a pattern increasingly relevant as AI training and inference demands collide with local infrastructure constraints and public opposition. This tactic signals how regional governance may become a bottleneck for high-stakes compute deployment, particularly when national security applications face grassroots friction over grid capacity and environmental impact.65
Multilingual medical benchmark exposes LLM performance gaps in non-English languages
A two-year multilingual medical benchmark reveals sharp performance cliffs for LLMs in non-English contexts. HealMed, built by 23 physicians across nine countries, tested nine languages on 9,000 expert-reviewed examples spanning multiple-choice, inference, and open-ended tasks. Proprietary models maintained stability across languages, while open-source and medical-specialist variants showed volatile, inconsistent degradation in low-resource settings. This work exposes a critical gap in model robustness for clinical deployment outside English-speaking regions, signaling that medical AI claims of global readiness remain premature.62

Generalist AI's GEN-1.5 learns robot tasks from single demonstrations
Generalist AI's GEN-1.5 represents a meaningful step toward practical robot learning at scale. Single-shot imitation learning has long been a bottleneck in robotics deployment; reducing the demonstration burden from dozens of examples to one fundamentally changes the economics of task adaptation in industrial and service robotics. This capability sits at the intersection of vision-language models and embodied AI, suggesting that foundation models trained on diverse sensorimotor data can now generalize across robot morphologies and environments with minimal fine-tuning. For robotics integrators and manufacturers, this lowers barriers to rapid task customization.73

Sutton argues synthetic data limits LLM scaling, proposes continuous learning agents instead
Richard Sutton, a Turing Award winner, challenges a core scaling assumption in modern LLM development: that synthetic data can substitute for real-world experience. He argues the world's infinite complexity makes any simulation fundamentally inadequate, with human expertise becoming the actual bottleneck rather than data availability. His counterargument pivots toward continuous learning agents that accumulate knowledge from live interaction rather than frozen training corpora. This critique strikes at infrastructure decisions already baked into billions in compute spending, potentially reshaping how labs think about data strategy versus agentic architectures.73