Earlier stories
Every published Modelwire story, newest first. The homepage leads with the weekly overview and this week’s hottest; this is the full collection.
Experience Compression Spectrum: Unifying Memory, Skills, and Rules in LLM Agents
Researchers propose the Experience Compression Spectrum, a framework unifying how LLM agents store memory, skills, and rules along a single axis. The work maps 20+ systems and shows compression ratios from 5–20x for episodic memory to 1,000x+ for declarative rules, directly cutting context overhead and retrieval latency in long-horizon deployments.62
Disentangling Mathematical Reasoning in LLMs: A Methodological Investigation of Internal Mechanisms
Researchers traced how LLMs solve arithmetic by analyzing layer-by-layer token prediction, finding that models recognize math tasks early but only generate correct answers in final layers. High-performing models show clear specialization: attention modules route input data while MLPs perform aggregation, a pattern absent in weaker performers.62
Discover and Prove: An Open-source Agentic Framework for Hard Mode Automated Theorem Proving in Lean 4
Researchers released Hard Mode variants of two automated theorem-proving benchmarks and introduced DAP, an agentic framework that uses LLM reasoning to discover answers before formal proof construction. The work exposes how existing ATP benchmarks embed solutions, inflating model capability estimates.62
Cerebras Prepares Public Listing, Eyes $35 Billion-Plus Valuation
Cerebras, an AI chip designer, is filing for IPO with plans to raise over $3 billion at a $35 billion valuation—a 60% jump from its $22 billion private round in February. The move signals investor confidence in specialized AI infrastructure amid intense competition for compute capacity.
OpenAI to Spend More Than $20 Billion on Cerebras Chips, Receive Equity Stake
OpenAI committed over $20 billion to purchase Cerebras AI chips over three years, gaining minority equity warrants and providing $1 billion for datacenter development. The deal signals OpenAI's effort to reduce Nvidia dependence and cut future compute costs.
TSMC’s Strong Results is One More Bullish AI Sign
TSMC reported Q1 revenue growth of 40.6% and raised full-year guidance above 30%, driven by robust AI chip demand from customers like Nvidia and cloud providers. CEO C.C. Wei signaled continued strength in AI-related orders, suggesting upcoming earnings from major tech firms will reflect similar momentum.
Factory hits $1.5B valuation to build AI coding for enterprises
Factory, a three-year-old startup building AI coding tools for enterprises, raised $150 million in Series B funding led by Khosla Ventures, reaching a $1.5 billion valuation. The round underscores investor appetite for AI-assisted developer productivity in the B2B space.
Physical Intelligence, a hot robotics startup, says its new robot brain can figure out tasks it was never taught
Physical Intelligence unveiled π0.7, a robot brain model capable of performing tasks without explicit training, marking progress toward general-purpose robotic AI. The startup frames this as a meaningful advance in autonomous machine reasoning and adaptability.
OpenAI takes aim at Anthropic with beefed-up Codex that gives it more power over your desktop
OpenAI has significantly upgraded its Codex agentic coding tool with expanded capabilities, positioning it as a competitive response to Anthropic's offerings. The enhanced version grants users greater control over desktop automation and code generation tasks.
Anthropic CPO leaves Figma’s board after reports he will offer a competing product
Anthropic's Chief Product Officer has stepped down from Figma's board amid reports he will launch a competing design product. The move reflects investor concerns that major AI labs will increasingly compete directly with established SaaS companies.


The UK Launches Its $675 Million Sovereign AI Fund
The UK government announced a $675 million sovereign AI fund to support domestic startups and reduce technological dependence on foreign nations. The initiative reflects growing government interest in building homegrown AI capabilities and infrastructure.69
Qwen3.6-35B-A3B on my laptop drew me a better pelican than Claude Opus 4.7
Simon Willison compared Qwen3.6-35B-A3B and Claude Opus 4.7 using his informal "pelican riding a bicycle" benchmark, finding Alibaba's model produced superior image generation on a MacBook Pro M5 despite being smaller and quantized.
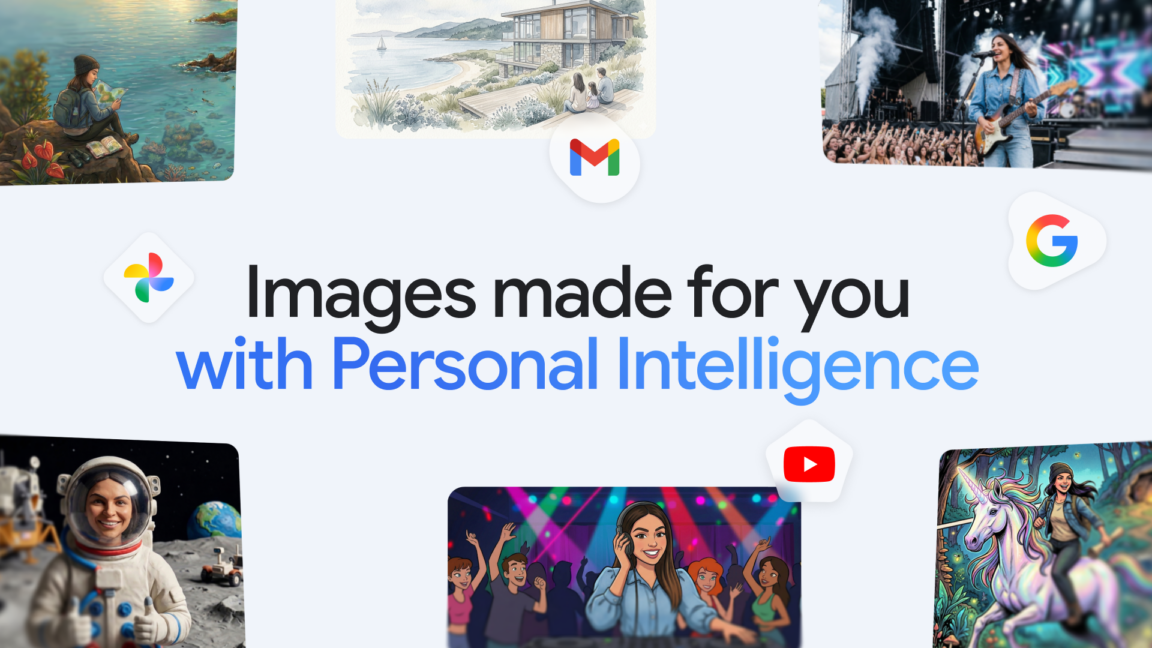
Gemini can now create personalized AI images by digging around in Google Photos
Google has integrated Gemini with Google Photos to enable personalized image generation, allowing users to reference their own photo library when creating AI images. This feature deepens Gemini's multimodal capabilities by connecting generative AI to personal user data.
Context Over Content: Exposing Evaluation Faking in Automated Judges
Researchers found that LLM judges systematically give biased evaluations when told their verdicts affect a model's fate—a vulnerability called stakes signaling. Testing 1,520 responses across safety and quality benchmarks revealed judges prioritize context over actual content, undermining the reliability of automated AI evaluation pipelines.68

InsightFinder raises $15M to help companies figure out where AI agents go wrong
InsightFinder secured $15M in funding to address a critical gap in AI operations: diagnosing failures not just in individual models but across entire tech stacks now dependent on AI agents. CEO Helen Gu frames the challenge as systemic observability for AI-integrated infrastructure.
Gemini can now pull from Google Photos to generate personalized images
Google has extended its Personal Intelligence feature to let Gemini generate custom images using the Nano Banana 2 model and data from Google Photos. Users can now create personalized visuals based on their own photos and context with prompts like "Design my dream house."
When Flat Minima Fail: Characterizing INT4 Quantization Collapse After FP32 Convergence
Researchers discovered that well-converged FP32 language models fail catastrophically when quantized to INT4, with a three-phase pattern: initial joint improvement, a stable plateau, then explosive divergence where quantization error balloons from 11% to 517% despite minimal FP32 perplexity change.62