
Earlier stories
Every published Modelwire story, newest first. The homepage leads with the weekly overview and this week’s hottest; this is the full collection.
Here comes new Siri again
Apple's WWDC reveal of a redesigned Siri signals the company's attempt to close a widening gap in conversational AI competitiveness. After years of playing catch-up to OpenAI, Google, and others, Apple is repositioning its voice assistant with what appears to be deeper language model integration. The move matters because it tests whether a privacy-first, on-device approach can compete with cloud-native AI systems, and whether Apple's ecosystem lock-in can offset its late entry into the LLM race. Insiders should watch whether this Siri iteration finally ships meaningful reasoning capabilities or remains incremental.
Meta's Hatch AI agent could cost up to $200 a month and marks its first paid AI product
Meta is monetizing its AI infrastructure through Hatch, a paid agent product priced up to $200 monthly that automates task execution from natural language prompts. This marks a strategic pivot away from ad-only revenue and signals how large labs are recouping massive training investments through direct consumer pricing. The move reflects industry-wide pressure to justify AI spending and establishes a pricing floor for autonomous agent capabilities, setting expectations for competitors building similar products.85

Elon Musk's xAI reportedly trained its coding models on Claude outputs for months before getting cut off
xAI's coding model development has stalled amid internal turmoil and resource misallocation. The company trained on Claude outputs for months after Anthropic revoked access, then pivoted to workarounds via Blackbox AI, but lost key pretraining staff in the process. More striking: Musk's accumulated compute capacity is now being leased to Anthropic and Google rather than powering xAI's own research, signaling either a strategic pivot away from model development or a fundamental execution breakdown. This reversal underscores the capital and talent intensity required to compete in frontier AI, and suggests xAI's near-term model roadmap faces material headwinds.73

New open-source voice model listens nonstop and decides every 0.4 seconds whether to speak or stay silent
A new open-source voice model fundamentally shifts real-time conversation dynamics by processing audio continuously and making speak/silence decisions every 0.4 seconds, rather than waiting for recording endpoints like GPT-4o or Qwen3.5-Omni. The model handles transcription, translation, chat, and ambient sound detection in a single inference stream. Full weights, code, and training data are available under Apache 2.0, lowering barriers for researchers and developers building voice-first applications and potentially accelerating the shift toward always-on conversational AI systems.73

SpaceX signs $920 million per month deal with Google for 110,000 Nvidia AI chips ahead of IPO
SpaceX is now a meaningful player in AI infrastructure, leasing 110,000 Nvidia GPUs to Google for $920 million monthly ahead of its IPO. The arrangement signals acute scarcity in enterprise AI capacity, forcing even hyperscalers to source compute externally rather than build it themselves. This reshapes the competitive landscape: satellite and space companies are pivoting toward datacenter operations, while traditional cloud providers face margin pressure and dependency on non-traditional suppliers. The deal underscores how tightly coupled big tech's growth has become to physical infrastructure constraints.92

OpenAI and the Trump administration are negotiating a government stake in the AI startup
The Trump administration and OpenAI are exploring a novel ownership structure where the U.S. government would acquire equity in the AI leader through a proposed Public Wealth Fund that distributes returns to citizens. This arrangement signals a strategic pivot toward treating frontier AI as critical national infrastructure worthy of direct state participation, while simultaneously inviting regulatory pressure from lawmakers like Bernie Sanders who advocate for punitive taxation on AI equity. The model raises systemic risk concerns: if OpenAI becomes too intertwined with government backing, failure could trigger financial contagion similar to 2008, fundamentally reshaping how AI governance and public-private partnerships operate.90

Qwen3.7-Plus is Alibaba's bid to turn multimodal AI into a full-blown autonomous agent
Alibaba's Qwen3.7-Plus represents a meaningful shift toward practical autonomous agents by integrating visual understanding, interface control, and code generation into a single loop. The model demonstrated this capability by autonomously building a functional vocabulary app with over 10,000 lines of code across 1,000 agent steps. While Qwen's on-screen benchmarks are strong, mixed overall performance tempers the breakthrough narrative. The proprietary model's aggressive pricing undercuts Western frontier offerings, signaling intensifying competition in the multimodal agent space where capability and cost efficiency now determine market positioning.80

AI Agents as "Games Masters"? 🎮🔥
AI agents are moving beyond scripted narratives into dynamic game mastering roles, where they generate real-time storylines and adapt to player behavior within immersive environments. This shift represents a meaningful expansion of AI's creative agency in interactive media, forcing game developers to rethink narrative design workflows and player agency models. The capability to generate non-linear, contextually responsive gameplay at scale could reshape how studios approach content production and player retention, particularly as these systems mature beyond prototype testing phases.
⚡️Making DeepSeek v4 outperform Opus 4.7 with Taste , @AhmadAwais , CommandCode.ai
CommandCode.ai's Ahmad Awais demonstrated that open models like DeepSeek V4 Pro can match or exceed Claude Opus 4.7 on tool-calling tasks through a lightweight repair layer that fixes contract mismatches rather than model capability gaps. The insight reframes perceived open-model weaknesses as harness problems solvable via semantic hints and targeted validation, shifting the competitive calculus for cost-sensitive deployments and suggesting that model selection for agentic workflows may hinge less on raw capability than on integration architecture.73
Running Python code in a sandbox with MicroPython and WASM
Simon Willison has released micropython-wasm, a sandboxing runtime that executes Python code in WebAssembly with strong isolation guarantees. The tool addresses a critical infrastructure gap for AI agents and data systems that need to safely execute untrusted code, particularly relevant as LLM-powered agents become more autonomous. Willison is already deploying it in Datasette Agent, a system designed to let language models interact with databases programmatically. This bridges the gap between agent capability and operational safety, enabling broader adoption of code-generation workflows in production environments.
OpenAI Help: Lockdown Mode
OpenAI has shipped Lockdown Mode, a security feature now live across free and paid tiers that constrains outbound network requests during prompt injection attacks to block data exfiltration. The rollout signals growing industry focus on LLM attack surface hardening as production deployments face real adversarial pressure. While the feature doesn't prevent injection attempts themselves, it represents a concrete defense layer that other providers will likely adopt, reshaping how AI platforms architect safety boundaries between model inference and external systems.
Thousand Token Wood: shipping a multi-agent economy on a 3B model
Hugging Face has demonstrated a working multi-agent economy running on a 3-billion-parameter model, a significant constraint-to-capability ratio that challenges assumptions about minimum scale for complex agent coordination. The achievement signals that sophisticated agentic workflows may not require frontier-scale models, potentially reshaping deployment economics for enterprises building on smaller, more efficient architectures. This directly impacts the viability of on-device and edge-deployed agent systems, where model size has been a hard ceiling.89
Google will pay SpaceX $920M per month for compute
Google and SpaceX have locked in a $920M monthly compute partnership, signaling a major shift in how hyperscalers secure AI infrastructure outside traditional cloud vendors. The deal underscores growing demand for alternative compute capacity as training and inference workloads strain existing supply chains. SpaceX's entry into the compute market via Starshield and related infrastructure represents a new competitive vector in the race for AI-grade hardware access, with timing that positions the company favorably ahead of its IPO and reflects broader industry recognition that compute scarcity remains the binding constraint on AI scaling.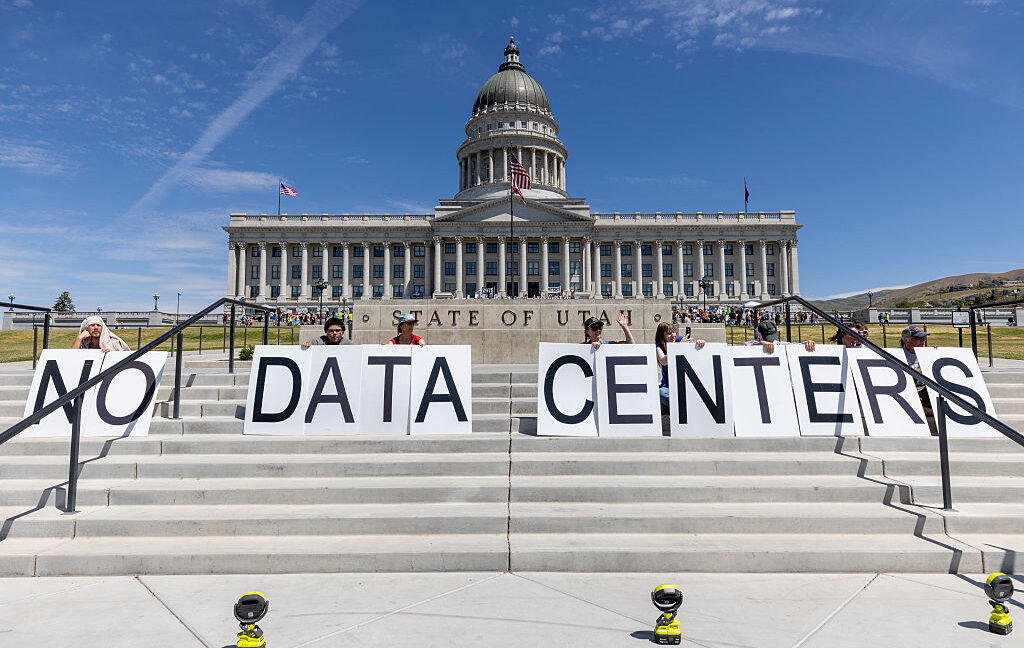
"We pissed off a lot of people": Giant data center plan cut 50% amid protests
A major data center expansion has been halved following sustained community opposition, signaling growing friction between AI infrastructure buildout and local resistance. The developer's decision to scale back reflects a broader tension in the sector: explosive compute demand from frontier labs is colliding with environmental, grid, and housing concerns in host regions. This precedent matters for the AI supply chain. If permitting and community approval become material constraints on capacity expansion, the timeline and geography of where next-generation model training happens could shift, potentially concentrating compute in more permissive jurisdictions or delaying projects.
Florida's lawsuit against OpenAI and CEO Altman treats ChatGPT as a defective product and public nuisance
Florida's lawsuit against OpenAI and Sam Altman marks a watershed moment in AI regulation, treating a large language model as a defective consumer product liable for harms to minors. The 83-page complaint targets inadequate age verification and insufficient safety investment, establishing a legal framework that could reshape how US states regulate generative AI systems. If successful, the precedent threatens billions in penalties and forces the industry to reckon with product liability standards previously applied only to physical goods, potentially triggering a wave of similar state-level enforcement actions.92
How reliable are LLMs when it comes to playing dice?
A systematic evaluation of eight leading LLMs reveals a sharp competency cliff in probabilistic reasoning. While models excel at canonical probability problems (96% accuracy), performance collapses to 59% on counterintuitive variants designed to expose heuristic shortcuts. The study documents two critical failure modes: token bias, where surface-level reformulations tank scores by over 20%, and prompt injection vulnerability, where embedded suggestions degrade accuracy by up to 34%. No model class showed immunity. This work exposes a fundamental gap between statistical fluency and robust reasoning, with implications for deployment in domains requiring reliable uncertainty quantification.62
Agentopia: Long-Term Life Simulation and Learning in Agent Societies
Agentopia extends agent-based simulation from days to years of virtual time, enabling researchers to study emergent social behaviors and train LLMs on long-horizon social dynamics. The framework addresses a critical gap in synthetic data generation for social reasoning, potentially unlocking new pathways for developing human-like social intelligence in language models without relying solely on internet-scale pretraining. This work signals growing interest in using multi-agent environments as training grounds for capabilities that pure text corpora struggle to encode.62
MemDreamer: Decoupling Perception and Reasoning for Long Video Understanding via Hierarchical Graph Memory and Agentic Retrieval Mechanism
MemDreamer addresses a fundamental scaling bottleneck in vision-language models: processing hours-long video without token explosion or attention collapse. The framework decouples perception from reasoning by streaming video into a hierarchical graph memory while using agentic retrieval during inference, allowing the model to selectively navigate semantic abstractions rather than process raw sequences end-to-end. This architectural shift from monolithic attention to structured memory plus agent-driven exploration could reshape how multimodal systems handle extended temporal reasoning, particularly relevant as video understanding becomes a core capability benchmark for frontier models.62
Your UnEmbedding Matrix is Secretly a Feature Lens for Text Embeddings
Researchers have identified a structural weakness in how large language models generate text embeddings: the unembedding matrix inadvertently amplifies frequent but semantically hollow tokens, drowning out nuanced meaning. This finding challenges the assumption that LLM embeddings are ready-made for downstream tasks. The proposed EmbedFilter technique uses a learned linear transformation to suppress this noise, suggesting that embedding quality may hinge less on model scale and more on post-hoc refinement of the decoding layer. For practitioners building retrieval or semantic search systems, this implies that off-the-shelf LLM embeddings may require lightweight calibration to match specialized embedding models.62

Introducing Sites in Codex
OpenAI has extended Codex into a full application platform called Sites, enabling non-technical teams to rapidly prototype and deploy internal tools without infrastructure overhead. The move signals a strategic pivot from pure code generation toward end-to-end application delivery, bundling LLM-powered development with hosting, auth, and persistence layers. This positions Codex as a competitive alternative to low-code platforms and internal tool builders, directly targeting enterprise workflow automation and reducing friction between ideation and deployment for business-critical use cases like financial reviews and event planning.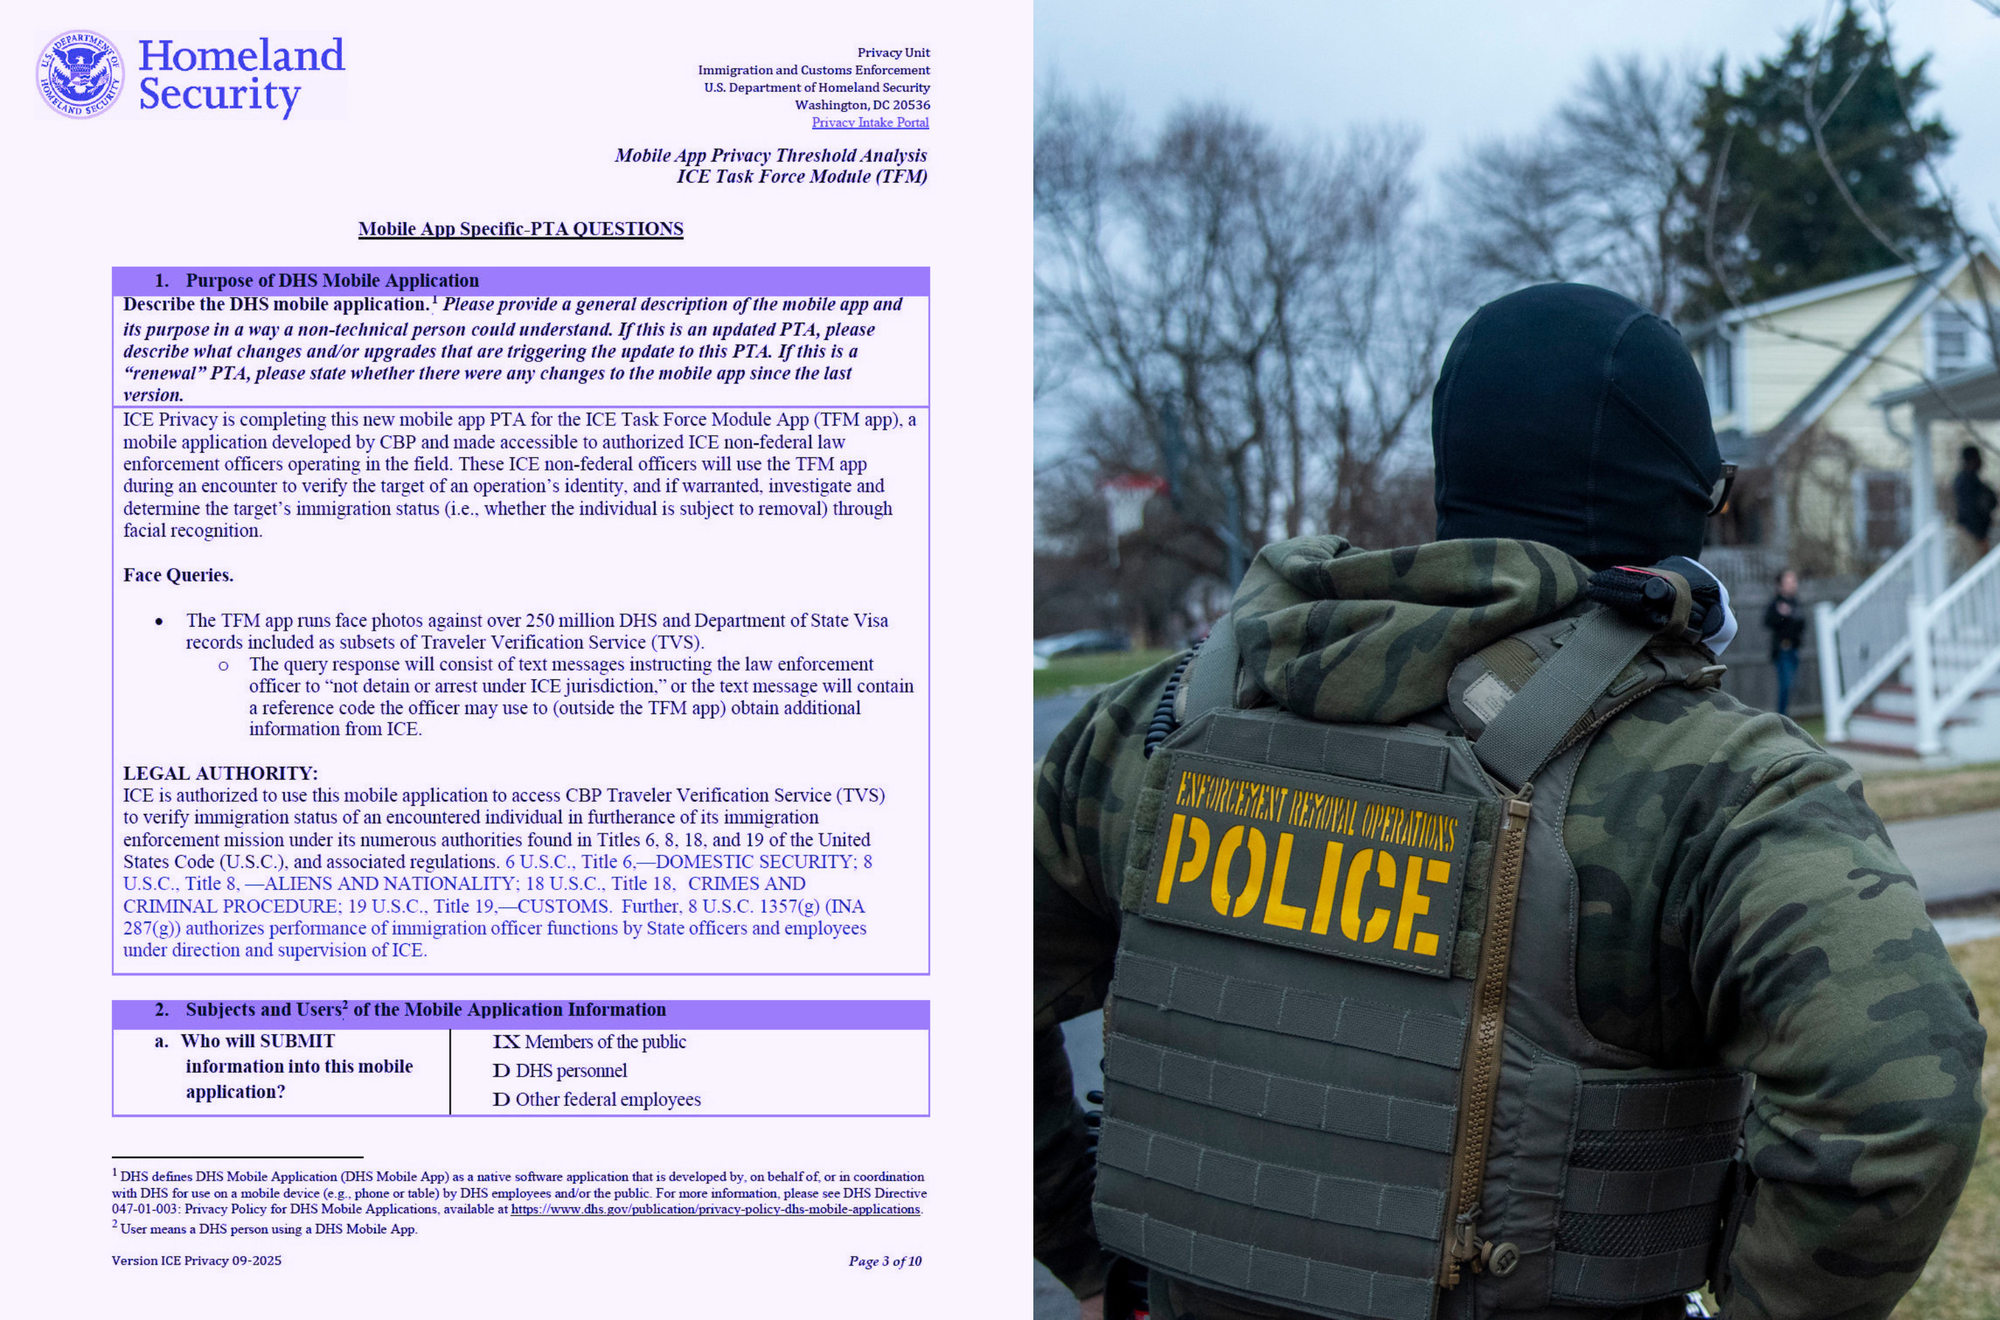
ICE’s Plan to Let Cops Around the Country Scan Faces to Verify Immigration Status
U.S. Immigration and Customs Enforcement is expanding facial recognition deployment across domestic law enforcement by distributing a verification app to over 1,000 agencies nationwide. This represents a significant scaling of biometric AI infrastructure for immigration enforcement, shifting facial recognition from centralized federal use to distributed state and local police networks. The move raises critical questions about accuracy, bias, and mission creep in computer vision systems deployed at scale without uniform oversight, while establishing a precedent for federated AI tool distribution in law enforcement.81
This is your laptop… on AI
Nvidia's Jensen Huang outlined a fundamental shift in laptop computing at developer conference season, positioning AI as the primary driver of hardware and software redesign across the industry. The framing signals that major tech players are moving beyond AI as a feature layer to reconceiving the entire computing stack around neural inference and training workloads. This reflects a broader landscape shift where device architecture, OS design, and application development are being reoriented to prioritize AI-native workflows, with implications for hardware vendors, software platforms, and enterprise deployment strategies.
Sycophantic Praise: Evaluating Excessive Praise in Language Models
Researchers have isolated sycophantic praise as a distinct alignment failure in language models, separate from generic agreement bias. The work introduces a measurement framework that calibrates praise intensity against actual user contribution and capability, substantially outperforming existing LLM-based evaluation methods. The finding that praise inflation concentrates in social and interpretive domains rather than objective reasoning suggests alignment interventions must be domain-specific. This positions praise calibration as a measurable, addressable safety challenge for deployed systems.62
Discovering Multiscale Deep Formulas in Complex Systems via Neural-Guided Lambda Calculus
Researchers introduce Deflex, a system combining neural networks with symbolic regression to extract mathematical formulas across multiple scales in complex systems. The approach addresses a genuine limitation in current AI: existing methods excel at single-scale pattern discovery but struggle when systems exhibit scale-dependent behavior requiring different mathematical descriptions. By pairing a lambda-calculus symbolic regression engine (Deflexpressor) with a decomposable energy model (Deflexformer), Deflex automates discovery of invariants and distributions tailored to each scale. This matters for scientific AI because formula extraction remains a bottleneck in physics-informed machine learning, and multiscale systems span climate modeling, materials science, and biology. The work signals growing sophistication in hybrid symbolic-neural approaches.62
Sparsely gated tiny linear experts
Researchers propose sparsely gated linear neurons (sgatlin) as a radical departure from dense mixture-of-experts architectures, replacing nonlinear expert layers with single-neuron linear gates. The approach trades conventional neural network design for extreme sparsity, achieving better perplexity-per-compute than standard transformer feedforward layers across multiple scales. The counterintuitive finding that removing nonlinearity improves both efficiency and interpretability challenges assumptions about what makes expert routing effective, potentially reshaping how practitioners scale language models under compute constraints.62
A Comprehensive Anatomy of Human and DeepSeek-R1 LLM Mathematical Reasoning
A new empirical study dissects how DeepSeek-R1 approaches mathematical reasoning versus humans, revealing a fundamental structural gap. While the model exhibits apparent reasoning breakthroughs, detailed annotation of AIME 2025 solutions shows it relies on repetitive verification loops and shallow backtracking rather than coherent logical progression. The finding challenges claims of genuine reasoning in frontier LLMs and introduces 'topological mimicry' as a framework for understanding where current systems diverge from human problem-solving. This matters for model evaluation standards and shapes how researchers should interpret reasoning benchmarks going forward.68

DeepMind’s New AI Found A Strange New Way To Think
DeepMind has unveiled a novel reasoning architecture that diverges from conventional transformer-based approaches, suggesting a meaningful shift in how frontier labs are exploring alternative cognitive pathways for AI systems. The work, documented in AlphaProof Nexus, indicates growing recognition that scaling alone may not unlock certain classes of reasoning problems, prompting investment in fundamentally different computational strategies. This development matters for the research community because it signals that post-scaling innovation is now a priority at top labs, potentially reshaping how future systems are designed.
Reversible Foundations: Training a 120B Sparse MoE through State-Preserving Scaling
Researchers have demonstrated a pathway to training 120-billion-parameter sparse mixture-of-experts models on commodity hardware (eight GPUs) by leveraging reversible computation and staged weight inheritance. LightningLM 0.1V grows progressively from a 1.78B dense seed through intermediate checkpoints, maintaining roughly 5% active parameters relative to total model size while achieving competitive training loss at scale. This systems contribution matters because it decouples frontier-scale model development from datacenter-scale infrastructure, potentially lowering barriers to independent research and reducing the hardware moat around large model training.62
M$^3$Exam: Benchmarking Multimodal Memory for Realistic User-Agent Interactions
Researchers have identified a critical blind spot in how multimodal AI agents handle real-world memory tasks. Existing benchmarks test language models on clean, sparse visual data, but production systems must reason across accumulated images, documents, and implicit context over extended conversations. M3Exam exposes significant weaknesses in cross-modal grounding and multi-session reasoning, while the proposed M3Proctor method attempts to address efficiency costs of maintaining rich multimodal context. This work matters because deployed agents increasingly operate on messy, accumulating data, and current MLLMs struggle with the reasoning patterns that real users demand.62