
Earlier stories
Every published Modelwire story, newest first. The homepage leads with the weekly overview and this week’s hottest; this is the full collection.
Thrive Holdings reaches $12B valuation on $2B enterprise AI funding
Thrive Holdings, an OpenAI-backed enterprise software company, has secured $2 billion in Series B funding at a $12 billion valuation, signaling sustained investor appetite for AI-native business applications. The round, led by SoftBank and D1 Capital Partners, reflects a broader shift toward deploying large language models in corporate workflows rather than consumer-facing interfaces. This valuation jump underscores how enterprise AI infrastructure remains a priority for institutional capital, even as the market consolidates around proven deployment patterns and integration challenges.
IIT Bombay and Adobe reverse-engineer LLM prompts from outputs
Researchers at IIT Bombay and Adobe have demonstrated a technique that reconstructs LLM prompts from model outputs with high fidelity, bypassing the need for model weights or architecture knowledge. The method, termed Previous-Token Prediction, works across different model families and exposes a critical vulnerability for enterprises protecting proprietary system prompts. This finding reshapes threat modeling for production LLM deployments, forcing teams to reconsider what information leaks through generated text and whether prompt secrecy remains a viable security boundary.85

Amazon lets Twitch creators block their content from AI training
Amazon has introduced opt-out controls for Twitch creators whose content feeds generative AI training pipelines. This move reflects mounting pressure on large platforms to offer data governance choices as foundation model development increasingly relies on scraped user-generated content. The capability to exclude streams, VODs, chats, and channel metadata from future training runs signals a shift toward consent-based data practices, though the scope remains limited to Amazon's own models and doesn't address historical training datasets already ingested.
Bengali speakers face 67:1 training deficit in AI infrastructure
A structural analysis of AI infrastructure reveals systematic disadvantages for underrepresented language speakers, using Bengali as a case study. The research identifies four critical failures: Bengali comprises less than 0.5% of web training data despite representing 4% of global population, creating a 67:1 token deficit relative to speaker population. These gaps originate upstream in corpus collection, tokenization design, and benchmark construction, not in model training itself. The findings challenge the narrative that scaling AI alone solves access gaps in low-connectivity regions, suggesting that infrastructure choices embed language inequality before deployment begins.62

Simulator collapse limits multi-agent RL generalization to real users
Researchers identify a critical failure mode in multi-agent RL systems where training policies against a single LLM simulator causes overfitting to that model's behavioral quirks, degrading real-world performance. The work formalizes simulator collapse as a theoretical problem and proposes dual solutions: Verbalized Sampling to expand simulator diversity at inference time, and Co-Training to broaden policy robustness during training. This addresses a fundamental gap in human-AI interaction systems where simulator fidelity directly constrains policy generalization, affecting deployment reliability across conversational agents and interactive learning systems.62
Enterprise AI agents stall without trustworthy data infrastructure
The deployment bottleneck for AI agents isn't capability, it's data infrastructure. MIT Technology Review reports that while enterprise adoption of autonomous agents is accelerating, organizations are discovering that ROI depends less on model sophistication than on foundational data quality and systems architecture. This signals a critical inflection point: the competitive advantage in agentic AI shifts from model labs to operational teams who can engineer reliable data pipelines and governance frameworks. For practitioners, this reframes the agent investment conversation from "which model" to "what data foundation do we need first."
Ring wearables emerge as AI's next frontier for ambient voice capture
Wearable AI is fragmenting into specialized form factors, with rings emerging as a new frontier for ambient thought capture. Following the success of transcribing earbuds and pendant recorders, Sandbar and competitors are positioning ring-based devices as the next layer in the AI-powered capture stack, targeting users who want frictionless logging of fleeting ideas outside formal meeting contexts. This signals a shift in how AI infrastructure vendors think about human-computer interaction: not as discrete productivity tools but as always-on cognitive augmentation woven into everyday objects. The category's viability hinges on whether voice-first interfaces can overcome privacy concerns and battery constraints that have plagued previous wearable waves.
VICBench dataset brings production-scale vulnerability data to security AI
Researchers have released VICBench, a dataset of 100 verified vulnerability-introducing commits tied to real CVEs across Python, Java, and C++. The benchmark addresses a critical gap in security AI evaluation: existing datasets lack the scale and complexity needed to train and test vulnerability detection systems at production fidelity. With patches averaging 38.6 lines and corresponding commits at 252.5 lines, VICBench represents substantially more realistic code patterns than prior benchmarks. This work matters because security-focused LLMs and code analysis tools depend on high-quality, diverse training data to catch real-world exploits. The dual human-expert and agentic annotation approach signals how the field is moving toward hybrid validation for safety-critical datasets.62

Radiologists report FDA-approved breast cancer AI tools underdeliver on recall reduction
FDA-approved AI systems for breast cancer screening are underperforming against radiologist expectations, according to a survey of 215 imaging specialists. While roughly half have adopted these tools, only 35 percent achieved the promised reduction in false recalls, compared to 59 percent who anticipated that outcome. This gap between marketed capability and clinical reality signals a broader tension in medical AI deployment: regulatory clearance does not guarantee practical utility or adoption momentum. The finding matters for the AI industry because it exposes how clinical validation pathways may not capture real-world performance variance, and it raises questions about how vendors communicate capability claims to healthcare institutions.73

Hugging Face adds custom embedding exports to OlmoEarth Studio
Hugging Face has expanded OlmoEarth Studio with custom embedding export functionality, enabling researchers and practitioners to generate task-specific vector representations for downstream applications. This capability addresses a practical gap in the open-source geospatial AI ecosystem, allowing users to move beyond pre-trained embeddings toward domain-optimized representations without retraining from scratch. The move signals growing maturity in specialized embedding workflows and reflects broader industry momentum toward modular, composable AI infrastructure where foundation models serve as building blocks rather than endpoints.64

Foundation model predicts drug combinations from few-shot screening data
ScreenShot represents a shift in how foundation models tackle domain-specific prediction tasks with limited data. By pretraining on 40 drug screening datasets covering thousands of drugs and samples, the hierarchical transformer learns generalizable patterns that enable few-shot predictions of drug combination efficacy without requiring per-cohort retraining or extensive molecular profiling. This approach directly addresses a bottleneck in pharmaceutical research where combinatorial screening remains prohibitively expensive. The architecture's alignment with nested screening data structures signals growing sophistication in task-specific model design, relevant to researchers building predictive systems for high-stakes domains where data scarcity and cost constraints are structural constraints.62
Long context training weakens models' internal knowledge retention
Researchers identify a fundamental trade-off in long-context LLM training: as models encounter abundant relevant information during pretraining, they shift from encoding knowledge into parameters toward relying on retrieval from context. This Information Abundance Paradox suggests that scaling context windows may inadvertently weaken a model's internal knowledge retention, forcing greater dependence on in-context information at inference time. The finding challenges the prevailing assumption that longer contexts uniformly improve model capability and has implications for how practitioners should balance context length against parametric capacity in production systems.62
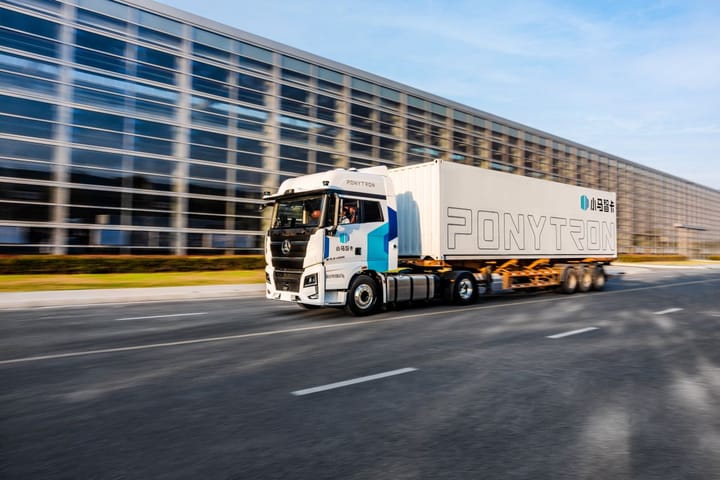
Chinese autonomous vehicle maker targets 100,000 self-driving trucks by 2030
A Chinese autonomous vehicle developer is targeting 100,000 self-driving trucks in commercial operation by 2030, signaling intensifying competition in logistics automation. The timeline underscores a strategic shift: while robotaxi development has captured headlines, heavy-duty autonomous systems remain technically harder and commercially slower to deploy. This deployment target, if achieved, would represent a major inflection point for supply-chain AI, forcing fleet operators and regulators to reckon with autonomous freight at scale. The announcement reflects growing confidence in perception and planning systems for highway trucking, even as the sector lags passenger vehicle autonomy in public visibility.61
Lovable reaches $13.3B valuation on $500M annual revenue pace
Lovable's $400M Series C round at a $13.3B valuation signals sustained investor confidence in AI-powered web development platforms. The startup's $500M annualized revenue run rate places it among the fastest-scaling AI infrastructure plays, validating the market for LLM-driven code generation and application building. This funding trajectory reflects broader venture appetite for AI tools that directly monetize developer productivity, even as the sector faces consolidation pressure from larger incumbents.
D'Addario reverses course, confirms Suno AI music in promotional video
D'Addario's two-week denial followed by admission of Suno-generated music in promotional content signals a critical inflection point for brand trust in the AI era. The company's initial deflection through technical explanations before capitulating to mounting evidence reveals how quickly synthetic media can erode corporate credibility when mishandled. This case matters beyond music: it demonstrates that disclosure gaps around AI-generated content now carry reputational costs that outweigh short-term production savings, forcing marketing teams across industries to recalibrate disclosure practices.
Gemini collapses to 1.9% market share as OpenAI and Anthropic dominate
Google's Gemini has collapsed from 12% to under 2% market share in recent months, while OpenAI and Anthropic consolidated dominance. Multiple independent tracking sources (Pangram, Similarweb, OpenRouter) confirm the trend, with ChatGPT holding over 50% and Claude surging to nearly 15%. The shift signals a critical inflection point in the consumer LLM market: Google's integration advantages and search distribution have failed to translate into sustained user adoption, leaving the company's AI strategy vulnerable as competitors lock in network effects and developer mindshare.85

Model rankings shift with token budget constraints, study finds
A large-scale empirical study reveals that LLM performance rankings are unstable across inference token budgets, with model orderings reversing significantly when generation limits change. Testing four models across three reasoning benchmarks with over 56,000 inferences, researchers found that 3-19% of tasks show non-monotonic accuracy patterns and that oracle analysis suggests up to 27.8 percentage points of untapped performance through budget-aware routing. This challenges the standard assumption that model comparisons remain valid across deployment conditions, with immediate implications for benchmarking methodology and production inference optimization where token budgets are a practical constraint.62
IBM commits $240M to open-model AI infrastructure with Together AI
IBM is investing $240 million in a Nvidia-powered AI cluster through a partnership with Together AI, signaling enterprise appetite for open-model infrastructure as demand shifts away from proprietary closed systems. The deal reflects a broader industry pivot toward decentralized AI compute and open-weight models, positioning IBM and Together AI to capture workloads from organizations seeking alternatives to centralized LLM providers. This capital commitment underscores how infrastructure vendors are betting on open models as a durable market segment, not a temporary trend.72
AI-assisted code creates knowledge gaps developers can't recover from
Florian Herrengt's analysis surfaces a structural risk in AI-assisted development: as teams delegate debugging and architecture decisions to LLMs, institutional knowledge erodes and systems become opaque even to their builders. The scenario depicts a failure mode where neither developer nor AI can trace data lineage or root cause, leaving projects fragile and unmaintainable. This challenges the productivity narrative around coding assistants, suggesting that wholesale outsourcing of reasoning tasks may hollow out mid-level engineering competence and create technical debt that no model can retrospectively untangle.
Specialized clinical RAG system outperforms frontier LLMs on India-focused health benchmark
VITA, a retrieval-augmented generation system designed for low- and middle-income healthcare settings, demonstrates that specialized, corpus-driven AI can match frontier LLMs on clinical benchmarks without requiring cutting-edge model weights. The system grounds itself in India-specific antimicrobial resistance data, national formulary constraints, and resource-limited protocols, challenging the assumption that general-purpose models dominate medical AI. With public benchmarks and scoring outputs, this work signals a shift toward localized, verifiable clinical AI that prioritizes regional medical knowledge over raw model scale, potentially reshaping how healthcare systems in underserved regions approach LLM deployment.62
LLM models show divergent cooperation strategies when signaled similarity
Researchers have developed the first systematic framework for testing how LLM agents respond to signals about their own similarity when facing strategic coordination problems like the Prisoner's Dilemma. The work reveals that different model families exhibit wildly divergent behaviors when given graded similarity information, with some maintaining consistent cooperation strategies across scenarios while others do not. This matters because as autonomous AI agents proliferate in real-world deployments, their ability to recognize and exploit shared decision-making patterns will shape whether multi-agent systems converge on mutually beneficial outcomes or defect. The findings suggest that monocultural AI ecosystems may not automatically cooperate as prior theory predicted, and that model architecture itself is a hidden variable in agent coordination.62
Meta's superintelligence bet faces public and industry skepticism
Meta's push toward superintelligent AI systems reflects a strategic divergence from industry consensus on safe, aligned development. The podcast examines tensions between Zuckerberg's vision of transformative AI capability and public skepticism about its desirability, while also surfacing broader ecosystem concerns: deceptive AI-as-human-content practices and infrastructure shifts like the Flock-to-Axon migration. For insiders, this signals how leading labs are navigating capability ambitions amid reputational and technical headwinds.65
Protein language models hide task-critical data in middle layers
Researchers systematically probed 13 protein language models across 15 downstream tasks to challenge the assumption that final-layer embeddings are optimal for biological inference. By training probe classifiers on intermediate layers and analyzing latent space geometry, they discovered that task-relevant information distributes unevenly across model depth, suggesting practitioners may be discarding useful signal. This finding reshapes how computational biologists should extract value from pretrained PLMs, potentially improving performance on drug discovery, mutation prediction, and structure inference without retraining.62

MedCLIP shortcuts undermine chest X-ray model robustness across layers
Researchers have exposed a critical vulnerability in medical vision-language models: CLIP-based systems like MedCLIP exploit dataset shortcuts rather than learning robust diagnostic patterns. By instrumenting ResNet-50 with 17 probes across layers, the team traced how models achieve high accuracy on chest X-ray tasks (pneumothorax, cardiomegaly) while relying on spurious correlations invisible to standard evaluation. This finding matters because medical AI deployment assumes learned features generalize across hospitals and populations. The layer-wise analysis reveals shortcuts emerge early and persist, suggesting current calibration methods mask brittle decision-making. For practitioners, this signals that SOTA metrics on benchmark datasets may not predict real-world reliability in clinical settings.62
Study links Meta smart glasses to coordinated harassment campaigns
Research documenting how influencers weaponize smart glasses for covert recording reveals a critical gap between hardware capability and platform governance. The study connects Meta's wearable devices to real-world harassment campaigns, exposing how consumer AI hardware can amplify non-consensual content creation at scale. This underscores an emerging tension: as AR/VR glasses become mainstream, the absence of robust detection and consent mechanisms leaves vulnerable populations exposed to coordinated abuse networks that exploit the devices' recording opacity.69

Google DeepMind releases sign language to text model for accessibility
Google DeepMind has deployed a sign-language-to-text model that converts visual sign input into written language, expanding accessibility infrastructure for Deaf and hard of hearing communities. This represents a meaningful shift in how multimodal AI systems address communication barriers beyond speech, positioning computer vision and language models as tools for linguistic diversity rather than standardization. The move signals growing investment in underserved accessibility use cases and demonstrates how frontier labs are applying foundation model capabilities to real-world inclusion challenges.
Hugging Face releases 3B vision-language model for edge deployment
Hugging Face has released LFM2.5-VL-3B, a compact vision-language model designed to bring multimodal capabilities to edge devices without sacrificing speed or accuracy. The 3B parameter footprint positions this as a practical alternative to larger models for on-device inference, addressing a growing demand from developers building AI applications with strict latency and compute constraints. This release reflects the broader industry shift toward efficient model architectures that democratize advanced vision capabilities beyond cloud infrastructure, enabling real-time applications in mobile, IoT, and embedded systems where bandwidth and power consumption are critical constraints.77

Google embeds generative AI across Pixel 11 camera and content tools
Google's Pixel 11 integrates multiple on-device AI capabilities into its camera stack, signaling a shift toward embedding generative and computational photography models directly in consumer hardware rather than relying on cloud processing. Magic Capture and Instant Night Sight represent advances in real-time image synthesis and low-light enhancement, while a built-in teleprompter suggests Google is expanding AI beyond photography into content creation workflows. This move reflects the broader industry trend of pushing inference to edge devices, reducing latency and privacy concerns while creating a differentiated hardware-software bundle that competitors must match.65
Anthropic names first legal-focused executive to expand Claude in law firms
Anthropic has created a dedicated legal vertical leadership role, signaling serious commitment to enterprise AI deployment beyond research. Robert Mahari's appointment as Head of Claude for Legal reflects a broader industry shift toward vertical specialization, where frontier labs build domain-specific go-to-market strategies rather than leaving adoption to third parties. This move matters because it establishes a template for how Claude competes with specialized legal AI vendors and positions Anthropic to capture high-value professional services workflows. The legal sector's regulatory scrutiny and liability concerns make it a proving ground for responsible AI deployment at scale.73