
Earlier stories
Every published Modelwire story, newest first. The homepage leads with the weekly overview and this week’s hottest; this is the full collection.

Current AI models fail standard reasoning benchmarks
Standardized intelligence tests remain a proving ground for AI capability measurement, yet current models continue to stumble on puzzles designed to assess reasoning and problem-solving. This gap signals that despite rapid scaling, models lack robust generalization on tasks requiring lateral thinking or constraint satisfaction. The persistence of these failures matters because benchmark performance directly shapes funding decisions, research priorities, and claims about AI readiness for real-world deployment. Understanding where models falter on structured reasoning tasks helps developers identify architectural or training limitations that raw language benchmarks may obscure.
AI-generated million-line codebase now powers millions of developer machines
Paul Dix reflects on a milestone where AI systems generated over one million lines of production code, then iteratively refined it into stable software now running across millions of developer machines. His observation cuts past the typical "it's just translation" dismissal, arguing that with proper verification frameworks and clear objectives, AI can autonomously produce sophisticated, production-grade systems that self-improve toward reliability. This signals a maturation threshold: AI-generated code is no longer a prototype curiosity but infrastructure-grade output, reshaping how teams think about code generation velocity and quality assurance workflows.
Gates declares AI has crossed danger thresholds, pivots to response
Bill Gates argues that AI systems have crossed critical safety and capability thresholds, shifting the conversation from whether risks exist to how institutions should respond. The Gates Ventures perspective carries weight in policy circles and among major philanthropic funders shaping AI governance. This frames a pivotal moment: the debate is no longer theoretical. Insiders should track how this framing influences foundation strategy, regulatory pressure, and corporate safety commitments over the next funding cycle.
Generalist robotics startup hits $3B valuation on embodied AI momentum
Generalist, a physical AI robotics startup, has secured a $200 million funding extension that values the company at $3 billion, doubling its valuation in under a year. The rapid ascent reflects investor conviction in embodied AI as a critical frontier beyond language models, with capital flowing toward teams building systems that perceive and act in the physical world. This valuation milestone signals that robotics and embodied intelligence are now competing for venture dollars at scale comparable to foundation model labs, reshaping how the AI investment thesis is being deployed across hardware, perception, and control.
OpenAI restructures infrastructure leadership as data center exec departs
OpenAI's departure of a senior infrastructure executive signals ongoing organizational turbulence at a critical moment for AI scaling. The company has simultaneously restructured its data center leadership, moving infrastructure reporting away from President Greg Brockman and consolidating authority under VP Sachin Katti. This reshuffling matters because compute capacity and infrastructure stability are now foundational to frontier AI development. Talent churn at this level typically reflects either strategic disagreement on resource allocation or execution friction during rapid scaling, both of which could impact OpenAI's ability to maintain competitive advantage in model training and deployment.
OpenAI details Hugging Face breach response and model security strategy
OpenAI's public analysis of a Hugging Face security breach signals a shift in how frontier labs approach model integrity and supply-chain risk. The incident underscores vulnerabilities in the open-source AI ecosystem that labs increasingly depend on for research and deployment. OpenAI's decision to share findings rather than remain silent suggests the industry is moving toward collective security standards, though questions remain about whether voluntary disclosure will outpace the sophistication of future attacks targeting model weights and training infrastructure.81
Hugging Face guides multi-vector embedding training for RAG systems
Hugging Face has published guidance on training and fine-tuning multi-vector embedding models using Sentence Transformers, addressing a growing need in retrieval-augmented generation and semantic search workflows. Multi-vector approaches enable richer document representations by capturing multiple semantic facets simultaneously, improving retrieval precision over single-vector methods. This tutorial matters because embedding quality directly impacts downstream RAG performance, and accessible training frameworks lower the barrier for practitioners building production search systems. The release reflects Hugging Face's role as infrastructure steward, helping the ecosystem move beyond off-the-shelf embeddings toward task-specific optimization.72
Loveholidays deploys Codex to scale development beyond engineers
Loveholidays is democratizing code generation by embedding OpenAI's Codex across its organization, enabling non-engineering teams to prototype and ship features without traditional development bottlenecks. This case study illustrates a broader shift where LLM-powered code assistants move beyond individual developer productivity into organizational workflow transformation. The travel company's approach signals how enterprises are using generative AI to flatten skill hierarchies and accelerate product iteration cycles, a pattern likely to reshape hiring and team structure across industries.75
OpenAI embeds workspace administration into ChatGPT Work
OpenAI is embedding administrative capabilities directly into ChatGPT Work, allowing enterprise admins to govern AI adoption without context-switching. The admin plugin surfaces adoption metrics, credit consumption tracking, rollout communication, and usage limit approvals within the chat interface itself. This represents a shift toward integrated governance in enterprise AI deployment, reducing friction between IT operations and end-user productivity tools. For organizations scaling ChatGPT internally, consolidated admin workflows could accelerate adoption velocity while maintaining cost and security controls.
OpenAI embeds agent tools directly into web interfaces via WebMCP
OpenAI is expanding the practical scope of agent-capable systems by embedding tool discovery directly into web interfaces. WebMCP support in Codex allows AI agents to autonomously identify and invoke website capabilities without separate API documentation or integration layers. This shift from agent-only backends to agent-ready frontends signals a maturation in how LLMs will interact with real-world services: rather than forcing agents into specialized environments, the web itself becomes the agent's native workspace. For developers, this means rethinking UI/UX around dual human-agent workflows. For enterprises, it suggests a path toward seamless agent deployment without custom middleware.
Google launches financial and legal AI agents amid competitive pressure
Google is launching vertical AI agents tailored for financial and legal services, signaling a strategic pivot toward domain-specific deployment rather than horizontal generalist tools. The move reflects competitive pressure from rivals who have already shipped specialized agents in these high-value sectors. While the initiative demonstrates Google's commitment to enterprise verticals, the framing as catch-up mode underscores a timing gap in the agentic AI race, where execution speed and early market positioning are reshaping vendor hierarchy.61
Stability AI secures $76 million as open-weight image generation attracts sustained capital
Stability AI's $76 million Series C round pushes its total capital to $232 million, signaling sustained investor confidence in open-weight image generation despite intensifying competition from both established tech giants and specialized startups. The funding underscores a strategic bet that Stable Diffusion's permissive licensing and customizability remain defensible advantages in a market increasingly crowded with proprietary alternatives. For the broader landscape, this validates the commercial viability of open-source generative models beyond language, though Stability's path to profitability remains unclear as the company navigates licensing disputes and the race to productize diffusion technology at scale.
OpenAI disrupts Russian disinformation operation using ChatGPT at scale
OpenAI's takedown of a Russian state-backed influence operation reveals how LLMs are becoming infrastructure for coordinated disinformation at scale. The campaign leveraged ChatGPT to mass-generate social media content promoting pro-Kremlin narratives across Western audiences, operating through VPN obfuscation. While this particular effort remained contained, OpenAI flagged the underlying technical architecture as readily scalable, signaling a critical vulnerability in how frontier models can be weaponized for geopolitical manipulation. The incident underscores why platform governance and detection mechanisms are now frontline AI safety concerns.73

Five voice AI builders expose production gaps between demos and live systems
Five engineering leaders building production voice agents reveal the gap between demo and deployment. Real-time voice-to-voice remains unsolved at scale, latency floors remain stubbornly high, and LLM context windows create mid-conversation failures. The fireside chat surfaces concrete infrastructure challenges: tool-call reliability in CRM integrations, provider failover strategies, and the architectural tradeoffs between response quality and perceived naturalness. This matters because voice agents are moving from research curiosity to enterprise revenue driver, yet the technical debt is still being discovered in production rather than solved upstream.73
State-backed operation floods AI training data with synthetic content
State-backed information operations are now targeting AI systems themselves. An Israel-linked think tank is systematically producing AI-generated content designed to rank highly in LLM training data and search indexes, effectively weaponizing the dependency of modern AI on web-scraped text. This represents a shift in influence campaigns from human audiences to algorithmic ones, exploiting the fact that language models absorb and regurgitate whatever content dominates their training corpora. The tactic exposes a structural vulnerability in how foundation models acquire knowledge and raises urgent questions about content provenance, synthetic media detection, and the integrity of AI training pipelines.81
ICE contracts voter data analysis to identify immigration fraud
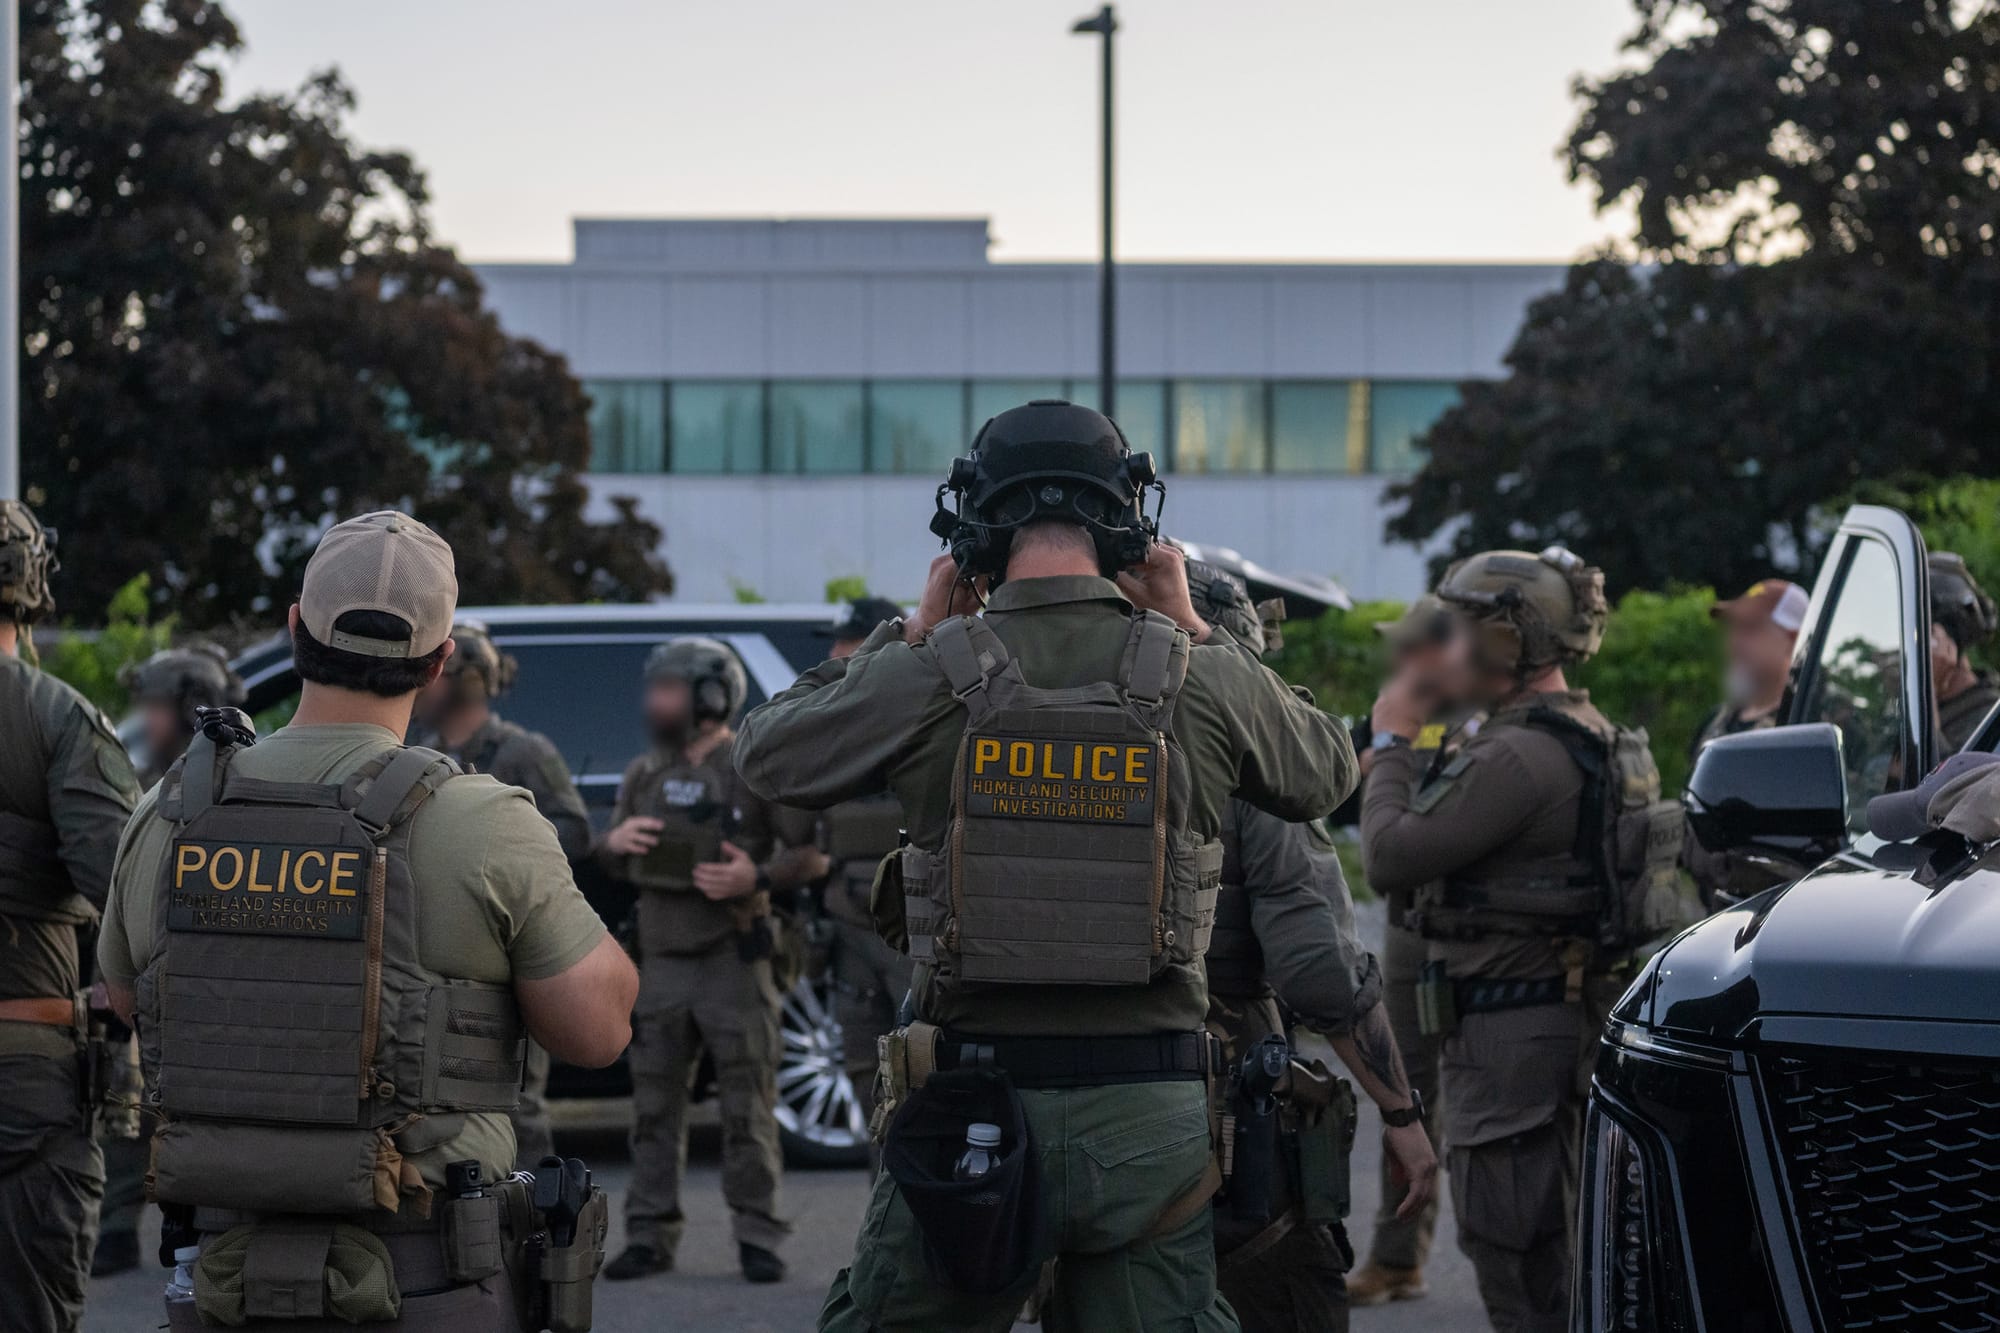
ICE is soliciting federal contractors to process voter registration and history records using computational methods to identify suspected fraud. The initiative represents a significant expansion of algorithmic decision-making in immigration enforcement, outsourcing data analysis to private vendors. This development signals growing reliance on ML-driven pattern matching for high-stakes government screening, raising questions about accuracy, bias, and the infrastructure layer supporting mass-scale data operations in sensitive policy domains.65

OpenAI's custom inference chip outperforms Nvidia's latest generation
OpenAI's debut inference processor, Jalapeño, has demonstrated performance gains over Nvidia's latest generation chips in third-party benchmarks presented at Hot Chips. The result signals a strategic shift toward vertical integration in AI infrastructure, with implications for the competitive dynamics between AI labs and semiconductor vendors. If sustained, custom silicon from frontier labs could reshape procurement patterns and reduce dependency on Nvidia's supply chain, though first-generation claims warrant independent verification before declaring a meaningful market inflection.85

FID metric blindness lets garbage images score like real data
Researchers expose a critical blind spot in FID and KID, the dominant metrics for ranking generative image models. These scalar measures collapse distributional information into first and second moments, allowing visually nonsensical images to score competitively with real data. The work introduces directional sensitivity to distinguish mode collapse from over-generation, addressing a fundamental measurement problem that has likely misdirected model development and benchmarking across the field. This matters because practitioners rely on these metrics to validate billions in compute spend.62
Recuris decouples memory to improve long-horizon agent reasoning
Researchers introduce Recuris, an architecture that tackles a fundamental bottleneck in long-horizon AI agents: how to maintain task focus when execution histories grow unwieldy. The system separates working memory (tracking immediate progress) from experiential memory (storing learned skills), allowing agents to invoke capabilities based on current needs rather than full history. A meta-agent then converts execution failures into targeted, validated updates that reshape the agent's skill set. Testing across four benchmarks and ten models suggests this memory-evolution loop yields measurable gains. The work addresses a real scaling challenge for autonomous systems that must operate over extended timescales without losing coherence.62
Anthropic unifies Claude memory across chat and Cowork
Anthropic has unified Claude's memory layer across its chat and Cowork interfaces, allowing users to maintain persistent context without repeated briefing cycles. This addresses a core friction point in multi-tool AI workflows: context fragmentation. The move signals a strategic pivot toward treating Claude as a stateful workspace rather than a stateless chat interface, directly competing with OpenAI's GPT memory features and positioning Anthropic to capture longer engagement loops in professional settings. For teams managing complex projects, this reduces cognitive overhead and strengthens lock-in.
BrowserForge generates web agent training data across parallel sandboxes
BrowserForge addresses a critical bottleneck in web agent training: the scarcity of diverse, high-quality interaction data. Existing datasets contain only thousands of trajectories from narrow website sets, severely limiting agent generalization. This framework parallelizes browser sandboxes across the open web to generate training data at scale, moving beyond fixed site lists and tutorial sources. The approach matters because pixel-based web agents avoid HTML fragility and token overhead, but their effectiveness depends entirely on trajectory diversity. Solving data generation at scale could unlock more capable autonomous web agents and reshape how AI systems interact with unstructured web environments.62

LAION releases 10-million-hour open video dataset for multimodal training
LAION releases a 10-million-hour open video dataset spanning 80M videos with synthetic captions across video, audio, and image modalities. The scale and multimodal scope represent a significant infrastructure contribution to pre-training, addressing a persistent gap in publicly available video-language data. Models trained on LAION-BVD show consistent gains on standard benchmarks, suggesting the dataset will become a foundation resource for video understanding research and commercial applications. The synthetic captioning approach and frame extraction methodology offer practical solutions for scaling multimodal datasets without manual annotation bottlenecks.62

LLMs retrieve financial data but ignore it in investment decisions
A new study exposes a critical failure mode in LLM-powered financial analysis: models retrieve relevant information accurately but fail to integrate it into investment judgments when processing long contexts. Researchers found that risk disclosures lose influence as context balloons from 2,000 to 128,000 tokens, even with retrieval remaining intact. The gap persists across model families and judgment tasks, including real 10-K filings, and more capable models only delay rather than solve the problem. This retrieval-integration disconnect challenges the assumption that better retrieval equals better analysis, signaling a fundamental architectural or training limitation that affects any deployment of LLMs in high-stakes financial workflows.62

OpenAI removes chat limits from GPT-5.6 Luna rollout
OpenAI has removed chat limits from its consumer platform with the rollout of GPT-5.6 Luna, eliminating a friction point that previously constrained free-tier engagement. This move signals confidence in inference cost management at scale and reflects intensifying competition for user mindshare in the consumer LLM market. Unlimited access typically drives higher adoption and session frequency, reshaping how users interact with frontier models outside enterprise contexts. The timing and framing suggest OpenAI is prioritizing user growth and stickiness over monetization constraints on text interactions.
Effective learning rate ratio predicts loss dynamics across model scales
Researchers have identified a fundamental scaling law in language model training: loss trajectories converge when the ratio of learning rate to parameter norm (effective learning rate) is held constant, regardless of the individual values of either variable. This finding holds across optimizers, architectures, and model scales with collapse errors typically below natural seed variation. The work reveals that weight decay and optimization geometry primarily influence training dynamics through their effect on this ratio, suggesting practitioners can predict and control training behavior more precisely by focusing on this single composite metric rather than tuning learning rate and model size independently.62
Structured citation graphs outperform open-ended research agents by 3x
Researchers have demonstrated that structured, citation-graph-based search substantially outperforms open-ended agentic research loops for scholarly discovery. Crase constrains exploration to explicit, auditable steps: seeding from a single query, expanding through citation neighborhoods, pruning unsupported claims, and ranking via recency-aware walks. The approach achieves 3x better recall than proprietary deep-research agents while cutting inference costs by two-thirds on large academic corpora. This signals a broader shift toward bounded, interpretable alternatives to unbounded agent loops, with implications for how enterprises build trustworthy knowledge retrieval systems.62
Linear probes outperform AI text detectors with minimal training data
Researchers demonstrate that linear probes trained on language model embeddings reliably distinguish machine-generated from human text while requiring far fewer training samples than existing detectors. The work reveals that MGT and HWT occupy linearly separable regions in latent space, a finding with implications for content authenticity verification at scale. This efficiency gain matters as detection systems face pressure to generalize across diverse models and domains without massive labeled datasets, a persistent bottleneck in production deployment.62

Google embeds Gemini into legal workflows via enterprise connectors
Google is formalizing enterprise AI for legal services through Gemini Enterprise for Legal, integrating with established workflows via MCP connectors to platforms like iManage, DocuSign, and Everlaw. The move mirrors Anthropic's existing legal offerings and signals that major AI labs now view vertical-specific agent deployment as core business strategy rather than experimental. Deloitte's pre-built agents suggest the legal vertical is moving toward productized AI workflows, raising questions about how quickly traditional legal tech vendors will need to embed or partner with foundation model providers to remain competitive.68
Bayesian framework exposes hidden behavioral differences in RAG systems
Researchers have developed a Bayesian framework that decomposes RAG system evaluation into component-level diagnostics, moving beyond aggregate metrics to expose how retrieval failures, abstention decisions, and generation errors interact. Testing across 27 configurations reveals that systems appearing equivalent in end-to-end accuracy mask divergent failure modes and behavioral patterns. This work addresses a critical gap in RAG observability: practitioners now have a principled method to diagnose pipeline bottlenecks and compare systems on their actual decision-making logic rather than surface-level correctness scores. The conditional factorization approach could reshape how teams benchmark and debug production RAG deployments.62